Streaming sends generated tokens to a client as they become available, rather than making the client wait for the complete response. This makes text-generation APIs feel more responsive. section 17.1.3 section 17.1.4
In a batched serving setup:
- A background model worker generates tokens for queued requests; an asynchronous generator yields each request’s tokens to its client as they arrive. section 17.1.4
FastAPI endpoint
The /generate endpoint queues the prompt and returns a StreamingResponse backed by a generator that streams the results. section 17.1.4
Figure 17.2 Dataflow with request batching and streaming
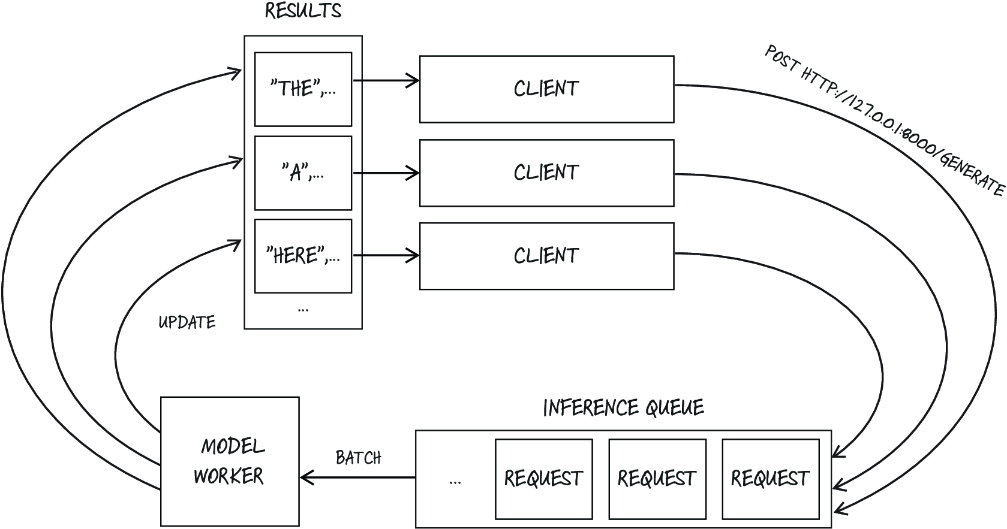
Trace how queued requests, batched model work, and streaming responses fit together. section 17.1.4


















