Streaming delivers a language model’s answer incrementally instead of making the user wait for the complete response. In retrieval workflows, it is most valuable during final answer generation, which can take substantially longer than search. Starting word-by-word output after initial processing reduces blank-screen time and improves perceived responsiveness. section 4.4
A production-oriented streaming workflow separates retrieval from answer delivery:
- Search agents retrieve relevant documents and return structured results before writing begins. section 4.1.2
- A writer agent receives the retrieved information and streams the final answer to the frontend. section 4.4
- Enable streaming in the model configuration with a stream setting, while constraining the writer to retrieved facts. section 4.4
Streaming a retrieved answer
A group chat routes a user question through search agents. After sufficient product information is retrieved, the writer assistant generates a concise response with temperature set to zero and streaming enabled, returning partial text one word at a time. section 4.4 section 4.1.2
Figure 4.11 After the 2 agents in the groupchat retrieve enough information to answer the user’s question, the structured search results flow to a Writer Agent, which streams back a concise answer to the user, one word at a time.
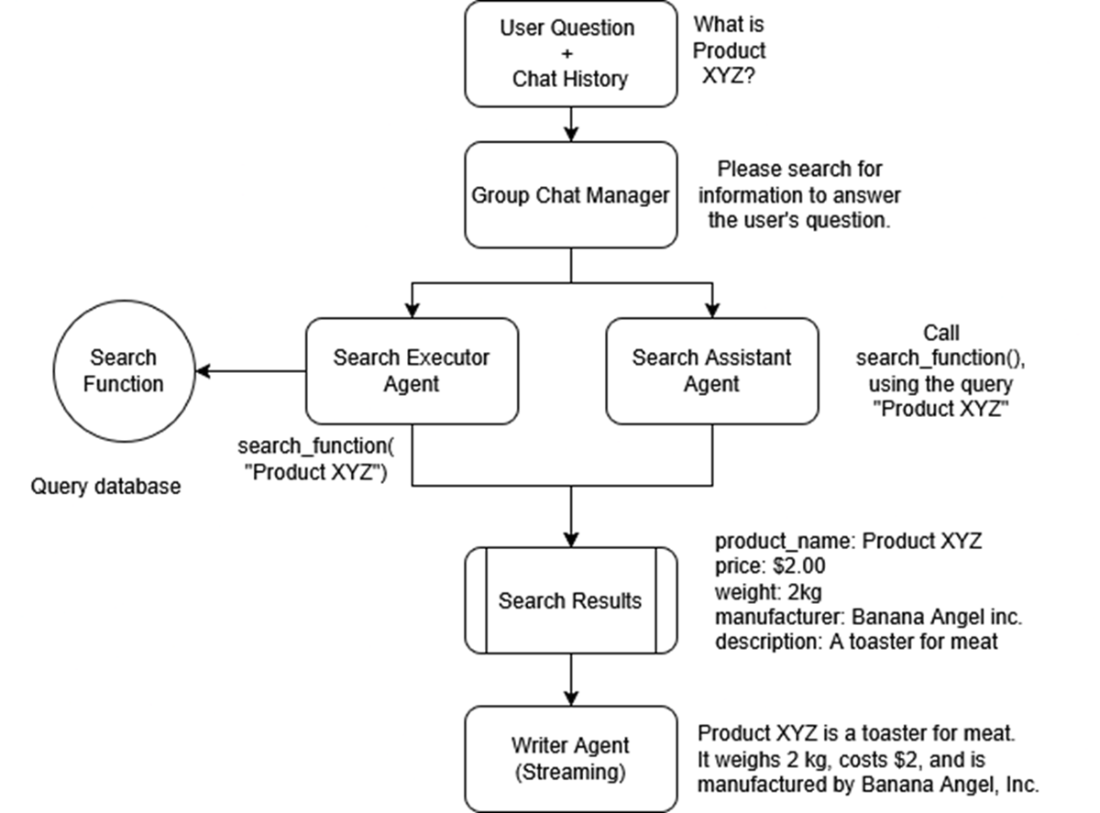
Follow the retrieval-to-writer flow showing structured search results becoming an incrementally delivered answer. section 4.4