DeepSeek is a family of openly available large language models built on Transformer foundations. Its released weights and detailed reports on data and training pipelines make it a useful starting point for studying how modern models are built. DeepSeek-R1 is a reasoning-focused model built on the earlier DeepSeek-V3 base model. section 1.1 section 1.2.1
A standard Transformer layer combines multi-head self-attention with a feed-forward network. DeepSeek replaces these components with Multi-Head Latent Attention (MLA) and a Mixture-of-Experts (MoE) structure to address scaling bottlenecks. section 1.2.1
The main techniques target different costs and capabilities:
- MLA reduces attention memory requirements. Its compressed key-value cache must be managed carefully, adding implementation complexity. section 1.2.1 section 1.4
- MoE routes tokens to specialized subnetworks, with computational load balanced across experts. section 1.4
- Multi-Token Prediction trains the model to predict multiple future tokens, with potential benefits for training and inference speed. section 1.2.1 section 1.4
- FP8 quantization uses an eight-bit floating-point format for weights and activations to improve computational efficiency. section 1.2.1 section 1.4
Figure 1.4 A simplified view of the DeepSeek model architecture. It modifies the standard Transformer by replacing the core components with Multi-Head Latent Attention (MLA) and a Mixture-of-Experts (MoE) layer. This design also utilizes RMS Norm (Root Mean Square Normalization) and a specialized Decoupled RoPE (Rotary Position Embedding).
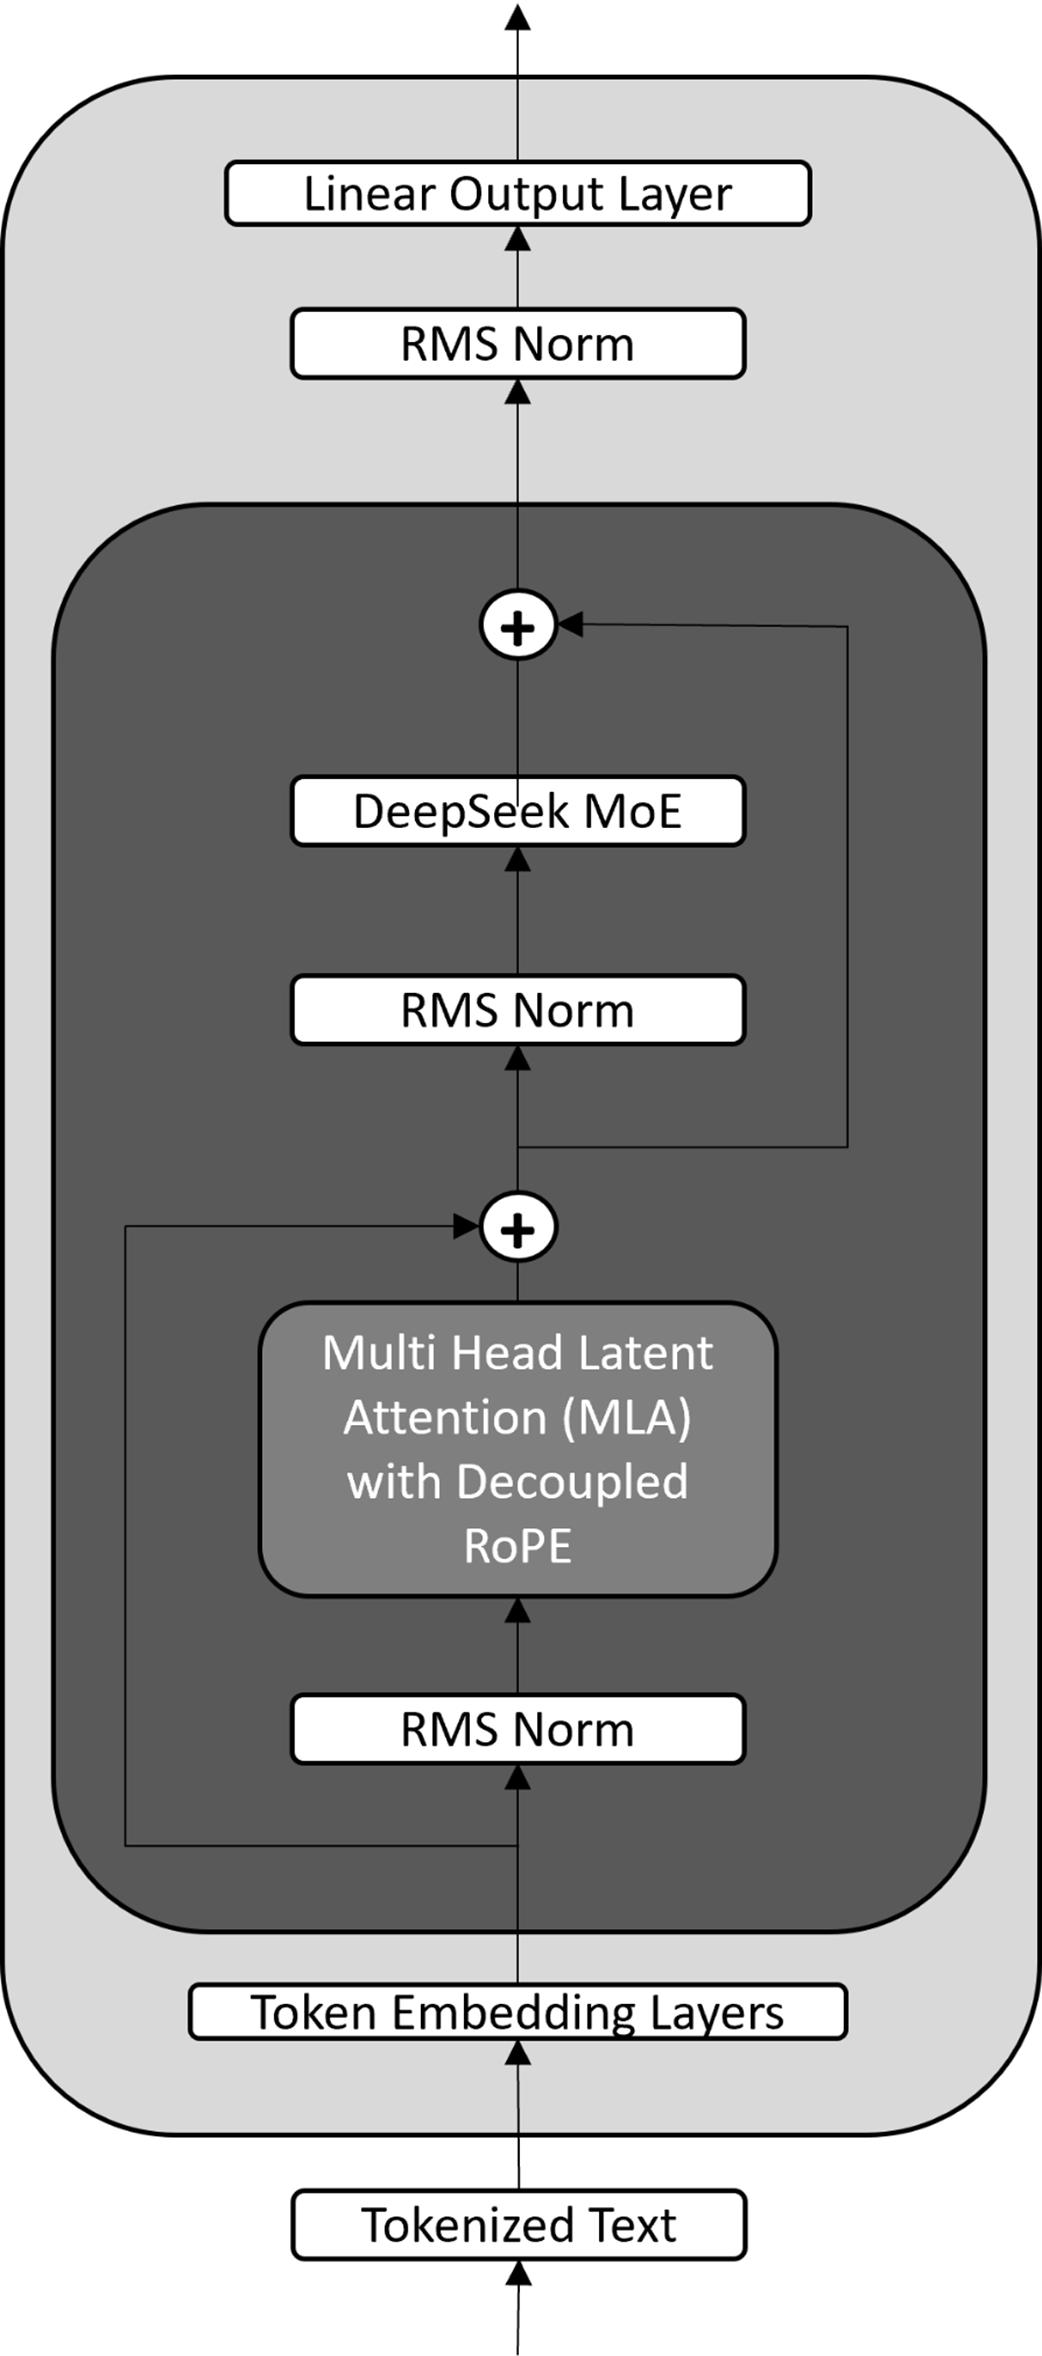
Compare the MLA and MoE components with a standard Transformer block; the diagram also locates RMS normalization and decoupled rotary position embedding. section 1.2.1
A scaled-down implementation can progress from the key-value cache to MLA and MoE, then to training techniques and post-training. The latter includes supervised fine-tuning, reinforcement learning, and distillation. Such a model is an educational approximation, not a reproduction of DeepSeek’s exact weights, proprietary training data, or production-scale infrastructure. section 1.3 section 1.4 section 1.0
