dlt is an open-source Python library for loading messy data from varied sources into destinations. Its pipeline function infers destination schemas, manages schema versions, and lets later processing remain unchanged across JSON, DataFrames, and iterable sources. section 8.2
A practical dlt workflow connects:
- Predefined sources such as SQL databases, GitHub, APIs, and chess.com. section 8.2
- A destination such as DuckDB, with metadata and inferred tables created automatically. section 8.2 section 8.2.2
- Selected resources passed to pipeline.run after defining the source and pipeline. section 8.2.2
Load chess profiles into DuckDB
Initialize a project with `dlt init chess duckdb`, then define `dlt.pipeline(pipeline_name="chess_pipeline", destination="duckdb", dataset_name="main")`. Select `players_profiles` from a chess.com source and run `pipeline.run(players_profiles)`. DuckDB contains the inferred `players_profiles` table alongside `_dlt_loads`, `_dlt_pipeline_state`, and `_dlt_version`. Adding `players_games` to the same run loads 589 game records. section 8.2.1 section 8.2.2
Figure 8.2 Ingesting data from chess.com into DuckDB
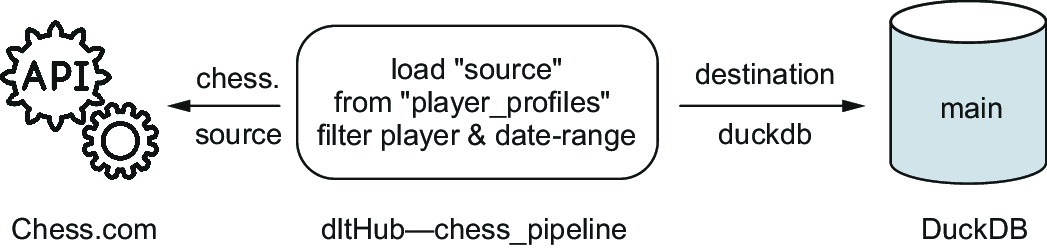
A pipeline diagram shows the flow from chess.com ingestion into DuckDB. section 8.2
