If ClaimAssist denies one group’s claims more often than another’s for the same claim type, that disparity needs investigation. Fairness evaluation tests observed system behavior for inequitable outcomes, including when a hosted LLM cannot be retrained. section 6.2.3
A repeatable evaluation loop can:
- Select critical journeys, such as denials, escalations, fraud flags, and summaries; create paired scenarios that differ in one sensitive signal. section 6.2.3
- Capture prompt and attribute variants, then reduce outputs to labels such as approve, deny, escalate, or require human review. section 6.2.3
- Compare outcome rates by group and investigate material differences, such as unequal denial rates for the same claim type. section 6.2.3
- Rerun tests after prompt or data changes. Specific prompt instructions create verifiable expectations, but monitoring and testing are still needed to catch failures. section 6.2.3 section 6.2.4
ClaimAssist in production
A scheduled CI job runs tests nightly and when prompts or retrieval sources change. LangFair structures runs and computes metrics; a dashboard supports weekly review. A warning-threshold breach blocks release and triggers manual bias review. A green dashboard is not proof of fairness: chosen groups, thresholds, or scenarios may miss important harms. section 6.2.3
Figure 6.5 Bias Testing Workflow for LLMs. A step-by-step process: generate prompts, collect LLM outputs, structure data, and analyze for bias using fairness toolkits.
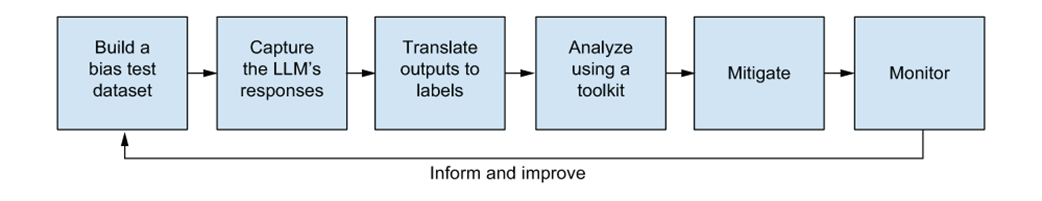
Use the workflow diagram to follow the sequence from prompt generation through output collection and analysis. section 6.2.3
Treat measurements as evidence to review, not a final fairness verdict. Check reference data for biased patterns; where sensitive attributes are available, protect them in storage for group monitoring while excluding them from model inputs. Review outputs for concerning patterns and route high-stakes decisions, such as fraud flags or denial letters, to a human. section 6.2.4

