GPT-4o is a multimodal generative AI model for working with text, images, speech, and video. It supports practical tasks such as image creation, visual analysis, and presentation coaching. section 2.2.1 section 17.1.3
Useful workplace applications include:
- Create simple logos and diagrams from plain-language descriptions. section 2.2.1
- Interpret user intent without requiring highly polished prompt-engineering skills. section 3.4.1
- Coach presentations by analyzing recordings, asking practice questions, and commenting on delivery, facial expressions, and body language. section 17.1.3
A simple image request
Prompt: “Create a simple cloud that looks relaxed and relieved, with a similarly simple yellow sun in the background.” The resulting logo closely matched the requested idea, illustrating how a concrete visual description can guide image generation. section 2.2.1
Figure 17.1 Screenshot from our OpenAI vision capabilities demo
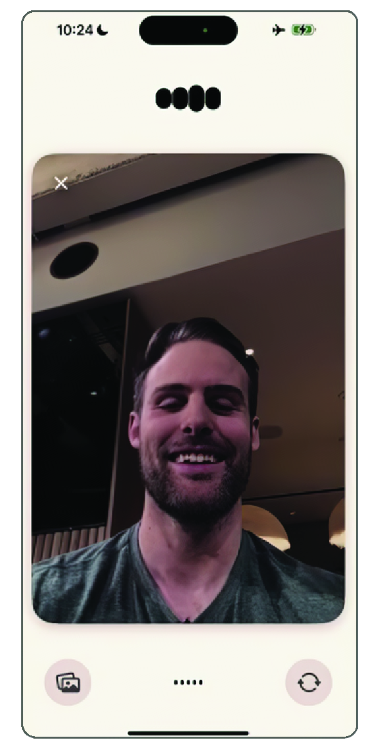
A vision demonstration shows GPT-4o identifying emotional state from facial expressions and body-language signals during a presentation. section 17.1.3



