A key represents what each position contains that might match a query. Attention compares queries with keys to decide which values deserve more weight, much like matching search text against indexed pages. section 9.5
In dot-product self-attention, learned transformations produce query and key vectors. Their dot products become attention scores; softmax normalizes those scores into weights that determine how strongly each value contributes to the output. section 9.5.1
Computing attention from query and key vectors
For an input x with shape [2, 3], create query, key, and value matrices with linear transformations. Compute q @ k.T, apply softmax across the scores, and multiply the resulting weights by v. Positions whose queries match keys more closely contribute more strongly through their values. section 9.5.1
Figure 9.7 Self attention, step-by-step from input to output
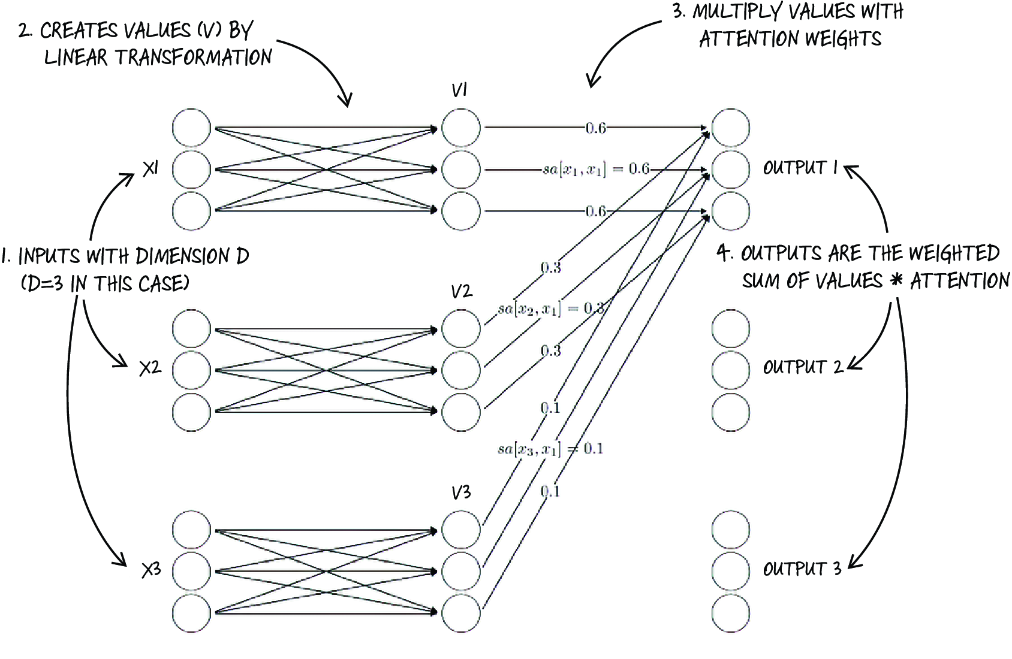
Follow the step-by-step flow from input positions through queries, keys, attention weights, and the output. section 9.5.1







