An attention key is a vector representing a possible answer that an attention query can match. Each key has a corresponding value vector, which supplies the information returned after matching. Unlike a Python dictionary, attention compares every key by similarity and combines their contributions rather than requiring one exact match. section 3.2.2
Predicting the next token
When predicting the next token, the current token acts as the query and preceding words act as keys. Attention weighs those keys by similarity, helping the model focus on relevant context. section 3.2.2
Figure 3.8 An example of how queries, keys, and values work inside a transformer compared to a Python dictionary. When a Python dictionary matches queries to keys, it needs an exact match to find the value, or it will return nothing. A transformer always returns something based on the most similar matches between queries and keys.
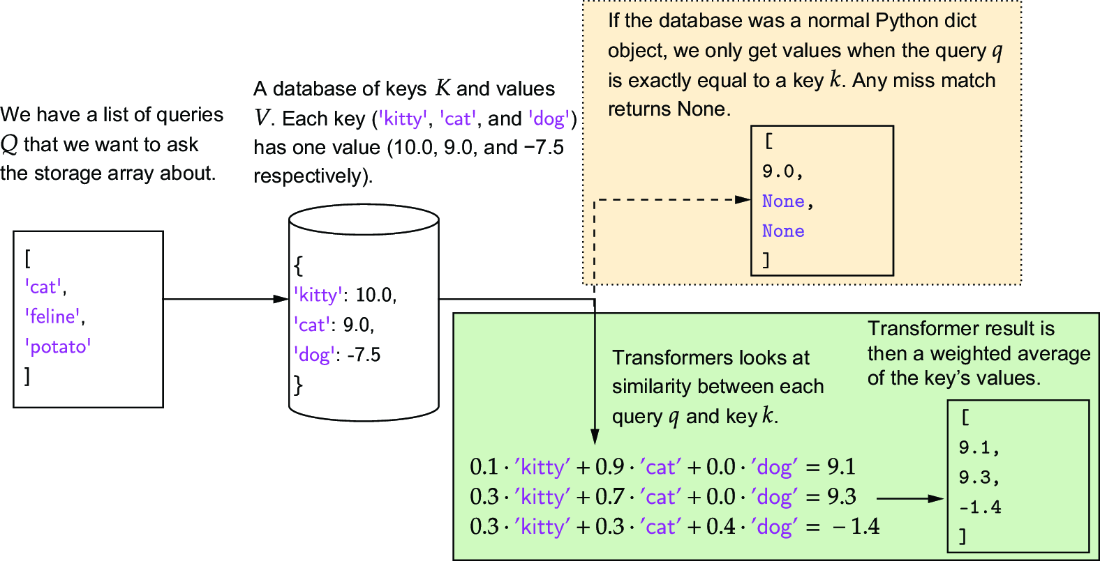
Compare exact dictionary lookup with transformer attention: a dictionary may return nothing without an exact key, while attention returns a weighted result from similar keys. section 3.2.2







