A team preparing a product presentation may need evidence scattered across a wiki, shared files, and email. Searching each repository separately slows the work, especially when nobody knows where the latest document lives. Similarity search helps locate information related to a query even when the document does not repeat the query’s exact words. It can power a search experience on its own or supply relevant documents to a retrieval-augmented generation (RAG) system. section 7.2.1 section 7.3
One approach is semantic search. An embedding model represents text as vectors that reflect meaning and context: words used in similar contexts tend to have similar representations. Documents are embedded and stored in an embedding database; a query can then be matched with semantically similar content. This offers a different route to relevance from keyword search, which depends on matching strings. It does not make keywords obsolete: combining semantic and lexical search, with metadata filters where useful, can make retrieval more precise. section 7.2 section 7.2.2 section 7.4
Figure 7.6 The process of semantic search
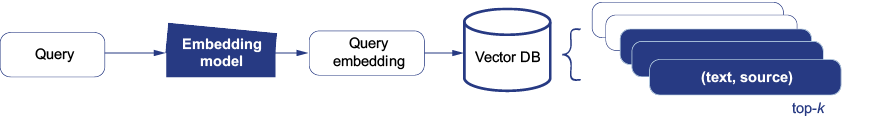
The semantic-search process connects an incoming query to relevant content stored as embeddings. section 7.2.2
Treat retrieval quality as a product decision, not just a model setting:
- Start with real tasks. Ask users whether results answer their query or force them to dig through irrelevant documents; have evaluators assess relevance more systematically as the system matures. section 7.2.3
- Choose chunks for the task. Shorter chunks can expose a specific statistic; longer ones can preserve the background needed for an open-ended report. Add document context when an isolated chunk would be ambiguous. section 7.2.4
- Investigate domain-specific misses before changing everything. Possible adjustments include the embedding model, chunking, lexical search, and metadata filters; evaluation helps identify which change is warranted. section 7.2.3 section 7.4
Finding case-study evidence
Suppose a marketer searches for “API integration case studies.” Reviewing whether the returned documents meet that intent reveals more than whether the system returned results quickly. If useful evidence is missing, the team can inspect retrieval and adjust it before relying on those results to generate customer-facing content. section 7.2.3 section 7.2.1
In RAG, retrieved documents become context in the prompt so a language model can answer directly rather than leaving users to synthesize a results list. Poor retrieval can still undermine a polished answer. Search therefore needs its own relevance checks, alongside checks that generated answers are grounded in the retrieved context. section 7.3 section 7.4





















