Language modeling uses patterns learned from text to estimate how likely sequences of words are. Rather than deciding whether a sentence is correct, a probabilistic language model ranks alternatives by how typical they are of its training data. Those probabilities can also support predictions of what word comes next. section 2.3.1
A simple approach estimates probabilities from counts of word sequences. Because considering every possible sentence is impractical, an n-gram model applies the Markov property: it approximates the next word’s probability using only a limited number of preceding words. Longer contexts can sharpen predictions, but require more data for reliable estimates. section 2.3.1 section 2.3.2
Estimating a continuation
To estimate the probability of “east” after “in the,” divide the count of “in the east” by the count of “in the.” The result is the fraction of occurrences of that context followed by “east.” section 2.3.2
Figure 2.2 A visual example of how n grams are extracted from a sentence. Each row shows overlapping windows of different lengths (bigrams, trigrams, and four-grams) sliding across the same sequence of words. As n increases, each unit captures more context, producing progressively larger segments of the original sentence.
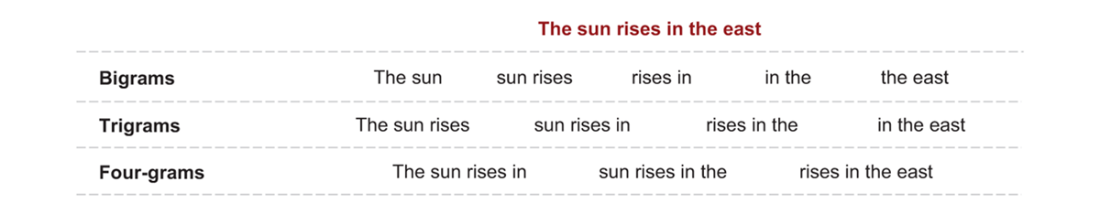
Overlapping n-gram windows show how increasing their length captures more context. section 2.3.2
Fluent output does not by itself establish factual accuracy or coherence. Generated responses can appear confident while lacking verifiable grounding, especially when relevant knowledge is sparse or ambiguous. External information and verification steps can reduce unsupported conclusions, but do not eliminate hallucinations entirely. section 2.6.6 section 6.5
Evaluation therefore depends on the task. Translation must balance faithfulness and natural phrasing, while summarization must condense without distortion. A single score or benchmark can conceal weaknesses on other dimensions. section 2.6.6






