Llama 2 is a family of autoregressive language models for text generation and understanding. Its 7B, 13B, and 70B variants illustrate how scaling increases capability while also increasing practical resource demands. section 10.1.1
Running Llama 2 locally involves:
- Accepting access terms and loading a Hugging Face authentication token. section 10.1.1
- Tokenizing a prompt, generating tokens with Transformers, and decoding them into text. section 10.1.1
- Planning for substantial storage, memory, download time, and generation latency. section 10.1.1
Prompted generation
A question-and-answer prompt can produce a direct response, such as answering that two cows and two bulls have 16 legs before explaining the arithmetic as 8. This inconsistency shows why generated answers require checking.
Figure 10.1 Scatterplot of the size vs. release date for LLMs with red diamond markers for proprietary models, such as GPT-4, with approx 1.5 trillion parameters and blue circles for open source models, such as Bloom, with almost 200 billion parameters
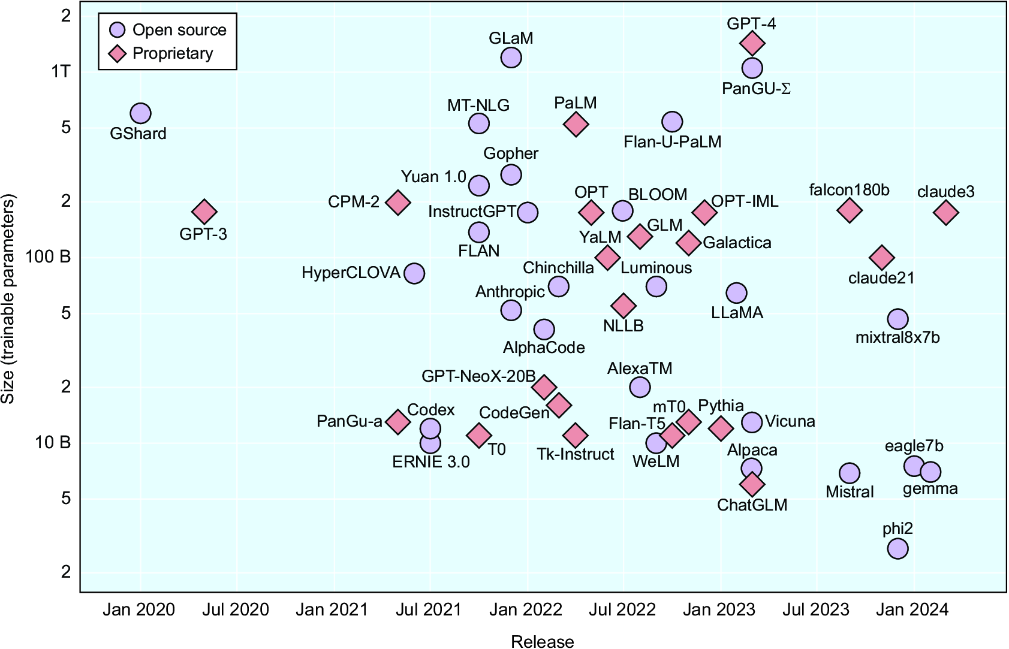
Compare open-source and proprietary language-model sizes and release dates. section 10.1.1




