LRU evicts the model that has gone unused for the longest time when a model cache reaches memory or GPU capacity. In multitenant prediction services, it supports model swapping so new requests can load required models without exhausting resources. section 6.3.2
Use LRU as part of a model-cache resource strategy:
- Evict cached models when the process approaches memory limits or available GPU resources are exhausted. section 6.3.2
- Combine eviction with model partitioning across instances to reduce cache misses and make model swapping less disruptive. section 6.3.2
- Keep caches separated by model type when input/output formats and preprocessing logic differ substantially. section 6.3.2
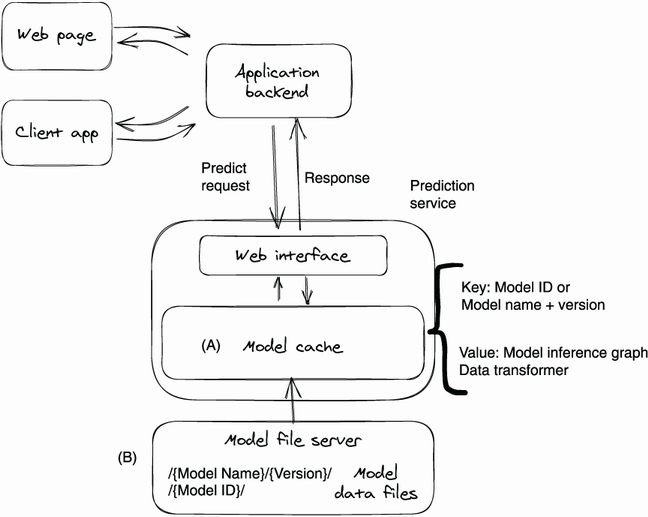
Use the architecture diagram to inspect how model caching and prediction requests fit within a multitenant prediction service. section 6.3.2

