A token limit is a configuration constraint that caps how much model context a request can carry. Session services must enforce it when assembling conversation history, because long conversations can exceed what a model processes. section 4.0
Allocate the available conversation budget across context tiers:
- Reserve space for model-managed memories containing critical structured facts that must not be lost. section 4.7.4
- Compress older conversation history into a rolling summary that preserves the essential narrative. section 4.7.4
- Keep recent messages verbatim so the current topic retains its nuance and conversational flow. section 4.7.4
- Tune the allocation for the application rather than treating the limit as a reason to pass every stored message. section 4.0 section 4.7.4
Long clinical conversation
A patient conversation may accumulate hundreds of messages. Instead of sending the entire history, the service places critical facts such as a penicillin allergy first, supplies a compact summary of earlier discussion, and appends the latest exchanges verbatim. section 4.0 section 4.7.4
Figure 4.9 Hierarchical memory combines three tiers of context. Model-managed memories store critical facts as structured key-value pairs. A rolling summary compresses older conversation history into a compact narrative. Recent messages remain verbatim to preserve nuance in the current exchange.
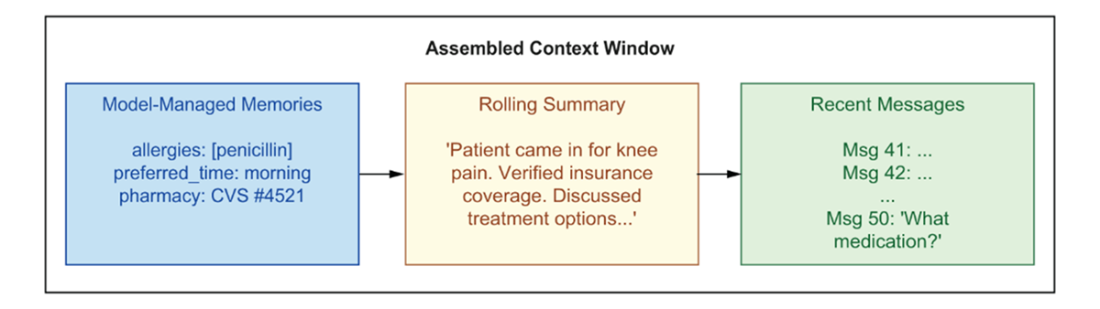
Use the three-tier diagram to inspect how structured memories, compressed history, and recent messages share one token budget. section 4.7.4











