For LLM inference, memory footprint is a practical constraint: extra bits increase memory traffic and energy per token, limiting throughput before arithmetic does. section 1.1 section 1.0
Quantization reduces the bits used to represent weights and activations, lowering memory footprint, bandwidth, and energy without changing model structure or semantics. These costs fall roughly in proportion to the bit reduction. section 1.0 section 1.4
Memory traffic scales with model and context
A 7B-parameter model moves roughly 15 GB through memory per generated token and uses nearly 2 joules per token. Model weights stay fixed as context grows, but the KV cache grows linearly; at 128K tokens, total traffic reaches 78 GB per token, 5.5 times the level at 512 tokens. section 1.4 section 1.1
Figure 1.1 Fetching data from HBM costs roughly 1,700× more energy than an INT8 multiply-add. This gap explains why inference systems are bottlenecked by memory, not compute.
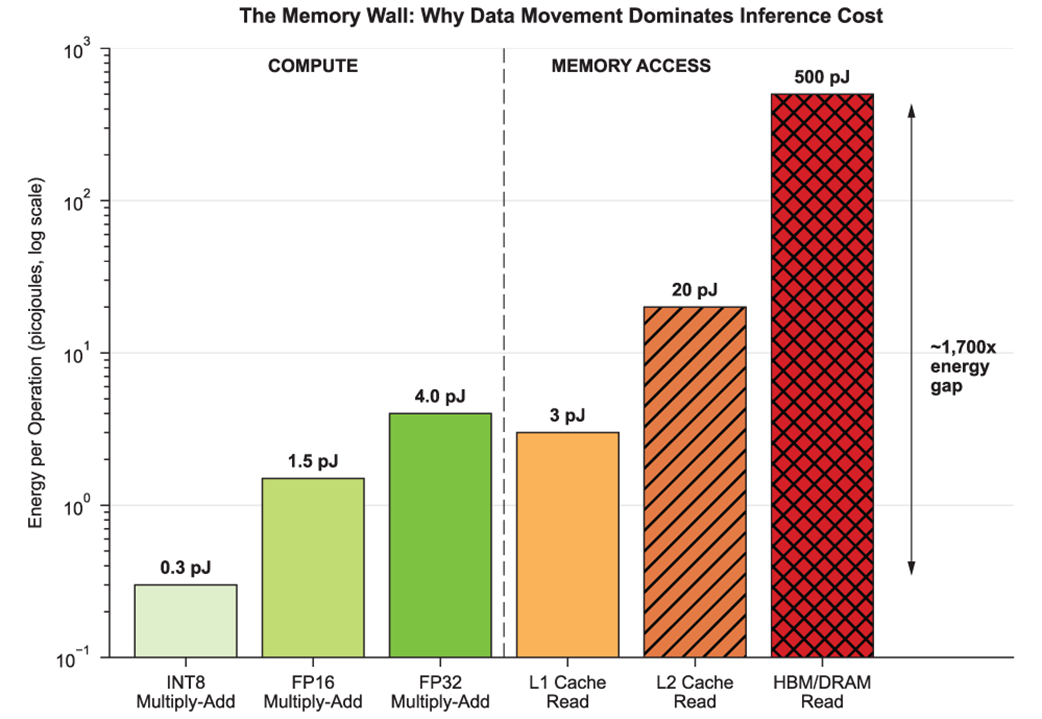
Compare the energy cost of fetching data from HBM with an INT8 multiply-add to see why data movement can dominate inference. section 1.1
Figure 1.2 Memory traffic per token as context length grows. Model weights (filled) stay constant, but the KV cache (hatched) scales linearly with context. At 128K tokens, total memory traffic reaches 78 GB per token—5.5× more than at 512 tokens.
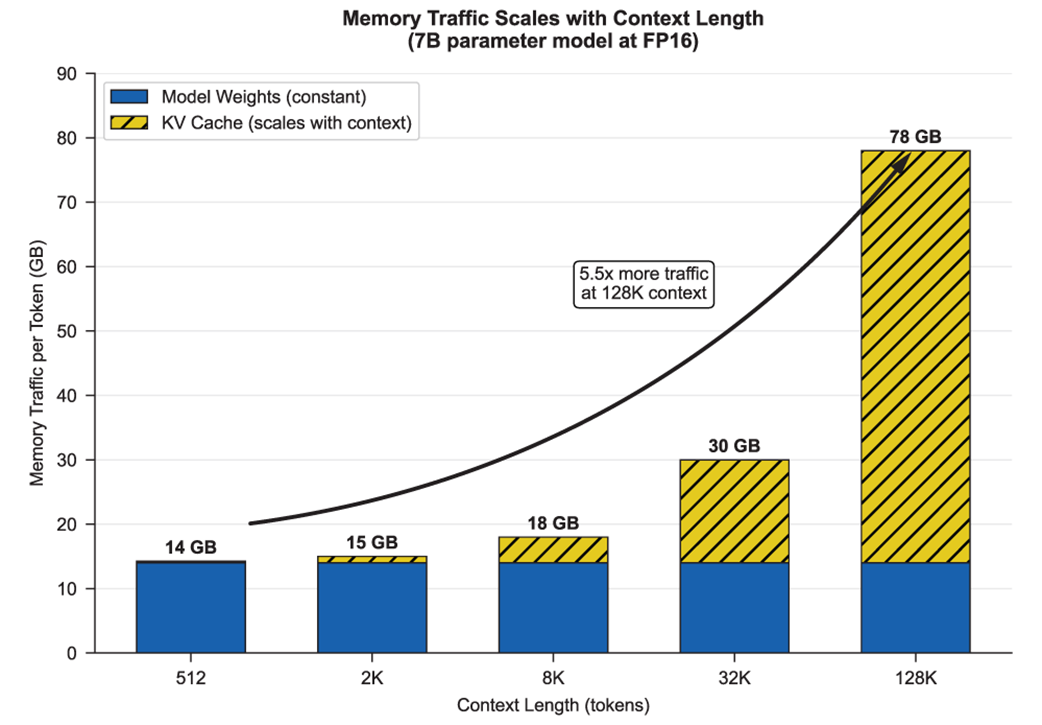
Trace how constant weight traffic and context-dependent KV-cache traffic combine as sequence length grows. section 1.1












