Moirai-MoE is a Moirai-based universal time-series forecaster that patches every frequency with the same fixed, nonoverlapping patch length. A decoder-only transformer generates forecast patches sequentially, while a sparse mixture-of-experts layer specializes in different time-series patterns. section 6.2 section 6.2.1 section 6.2.2
Its main implementation choices are:
- Uses one input projection for all frequencies instead of training frequency-specific embedding layers. section 6.2.1
- Routes tokens through a gating function and 32 feed-forward experts; at most two experts are activated simultaneously. section 6.2.2
- Generates one patch at a time, with each predicted patch informing the next prediction. section 6.2.2
- Provides small and base configurations with 117 million and 935 million parameters, respectively. section 6.2.3
Figure 6.5 Architecture of Moirai-MoE. Unlike the first version of Moirai, the new version uses a decoder-only transformer. Inside the decoder-only transformer, a gating function and a mixture-of-experts layer have been added. The gating function learns which expert to activate depending on the data, with a maximum of two experts being activated at the same time. The activation of an expert is indicated by a solid arrow.
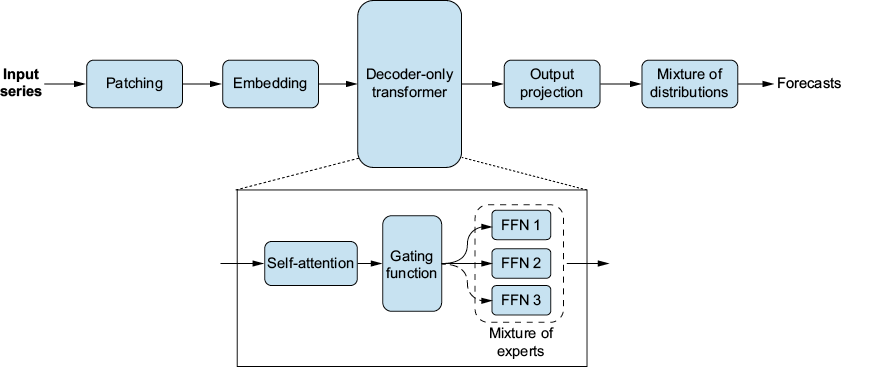
Use the architecture diagram to trace patching, decoder self-attention, gating, sparse expert activation, and forecast projection. section 6.2
