Multimodal AI processes and generates content across multiple modes, including text, images, audio, and video. In conversational interfaces, it combines visual information with a text prompt to produce a more comprehensive, context-aware response. section 3.4
A multimodal request typically moves through these application layers:
- The client provides a file-input interface for image selection. section 3.4.1
- The client encodes the image, such as with the FileReader API, and sends binary image data or an image upload alongside the textual prompt. section 3.4.1
- The LLM API forwards both modalities to a vision-capable model, which extracts visual meaning and combines it with the prompt. section 3.4.1
- The generated description or answer returns through the API response to the client application. section 3.4.1
Diagnosing a broken appliance
A user uploads an image of a broken appliance and asks, “What is this part, and how do I fix it?” The model identifies the part, analyzes its condition, and returns a context-aware answer. section 3.4.1
Figure 3.7 The process of sending an image alongside a text prompt to the OpenAI API and how the language model utilizes computer vision techniques to understand the image and generate a relevant text response
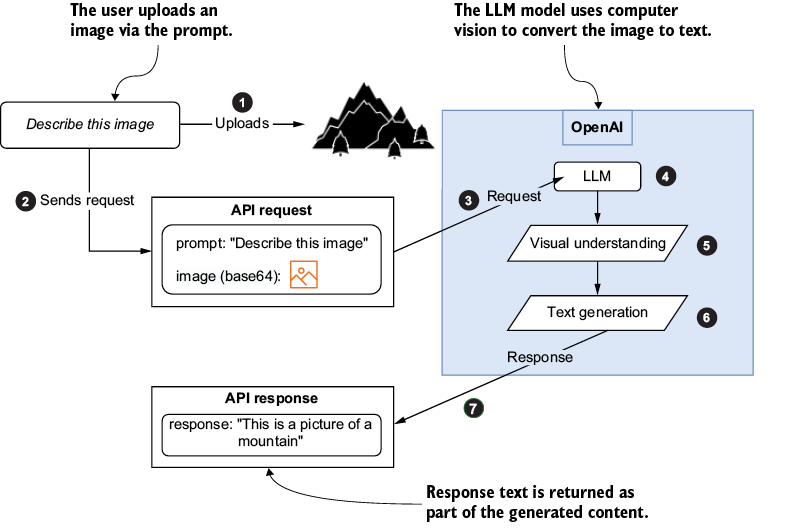
Use the workflow diagram to follow an image and text prompt from the client through the LLM API and back as a generated response. section 3.4.1










