A multimodal model processes multiple data types—such as text, images, audio, or video—within related tasks. Unlike single-modality models, it can correlate information across inputs, supporting applications such as content moderation, product recommendation, healthcare analysis, and situational awareness. section 4.1.5
A multimodal system may combine separate transformer blocks for image and text inputs with a combining layer. Repeated blocks are represented with notation such as Lx, Rx, and Nx, indicating stacked image, text, and combining components. section 4.1.5
Common applications combine complementary data types:
- Analyze text and images for web content moderation and sentiment analysis. section 4.1.5
- Recommend products using photographs together with text descriptions. section 4.1.5
- Combine patient histories with medical images for healthcare diagnosis. section 4.1.5
- Integrate radar, lidar, and camera data for self-driving situational awareness and decision-making. section 4.1.5
Image plus prompt
Provide an image of available produce with a related prompt asking what to cook. The model identifies ingredients and correlates them with the request, suggesting dishes such as guacamole, salsa, and avocado toast. section 4.1.5
Figure 4.9 Multimodal model design
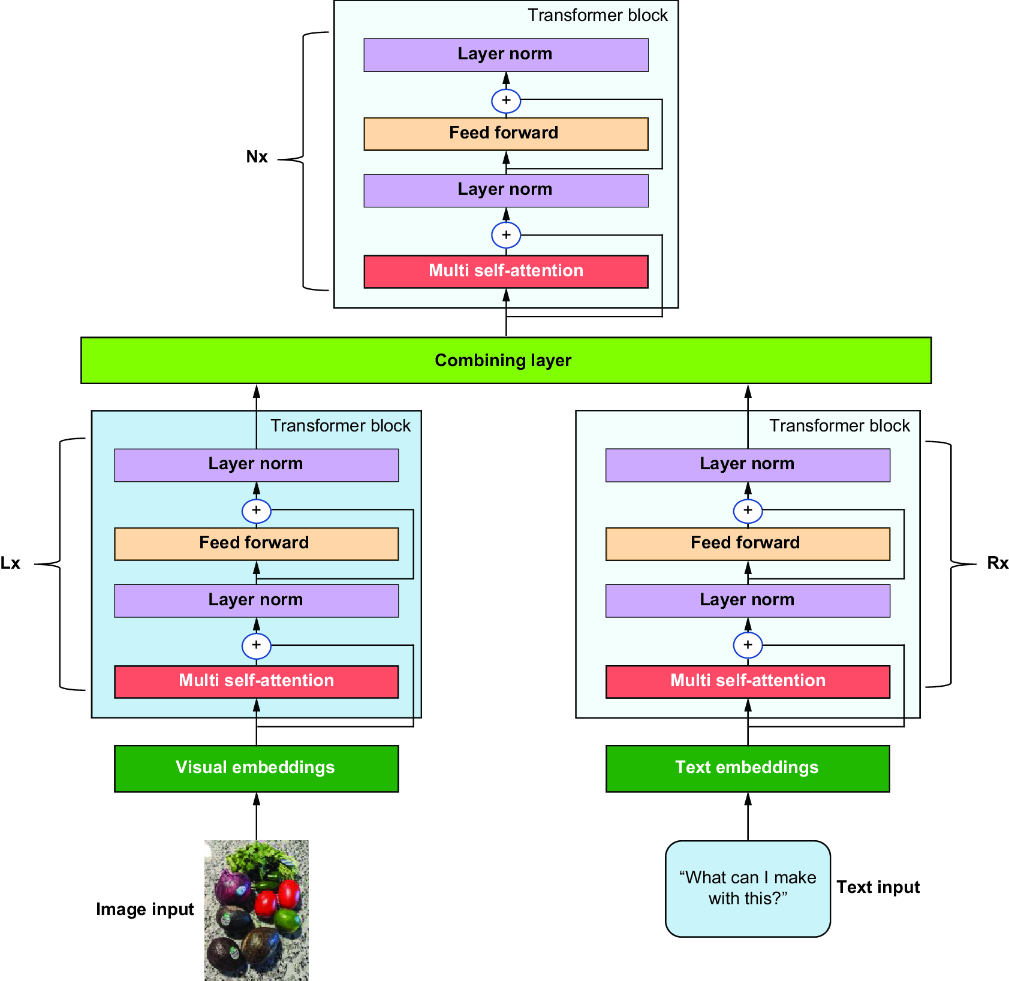
Use the architecture figure to inspect how image, text, and combining transformer blocks are arranged in a multimodal design. section 4.1.5










