One-hot encoding turns categories or words into binary vectors: each distinct value gets its own position, set to 1 for that value and 0 elsewhere. For categorical variables, this creates a column for each distinct class. section 2.7 section 7.13
Figure 2.36 Using one-hot encoding to convert categorical variables into numeric ones
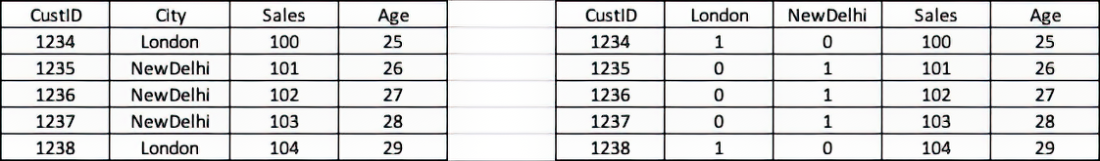
The city example shows categorical values represented in separate binary columns. section 2.7
Encoding a short sentence
For “It is raining heavily,” lowercase and alphabetize the words as heavily, is, it, raining. Encode “it” as [0, 0, 1, 0], “is” as [0, 1, 0, 0], “raining” as [0, 0, 0, 1], and “heavily” as [1, 0, 0, 0]. section 7.7
Encoding can let algorithms such as k-means use categorical inputs numerically. But many distinct categories create many mostly-zero columns; in text, large vocabularies also make vectors high-dimensional and sparse. The representation does not preserve relationships between words, so word embeddings offer an alternative for capturing context. section 2.7 section 7.13
For categorical data, pandas provides get_dummies() to convert variables into numeric columns. Check whether a variable offers useful variation: values that are mostly identical or all distinct may contribute little to analysis. section 11.6





