Performance optimization makes fast, reliable behavior a default property of software rather than a late rescue task. It shapes architecture, code, user flows, budgets, testing, and production monitoring across web, backend, mobile, and desktop systems. The aim is not a one-time speedup, but predictable performance as features, traffic, and teams grow. section 1.0 section 1.5
Reactive work commonly follows a decay cycle: teams prioritize features, small regressions accumulate, users experience slowdowns, complaints trigger emergency fixes, and normal shipping resumes. Hotfixes relieve the immediate symptom without preventing the next regression, leaving the system slower, more fragile, and less predictable over time. section 1.1 section 1.6
Figure 1.1 The performance decay cycle. Teams ship updates to production as usual. At some point, users complain about performance, the team panics and scrambles into action, rushes out a hotfix, then returns to shipping features. The arrows show how each stage leads inevitably to the next: the hotfix buys time but does not prevent future regressions, so the cycle repeats.
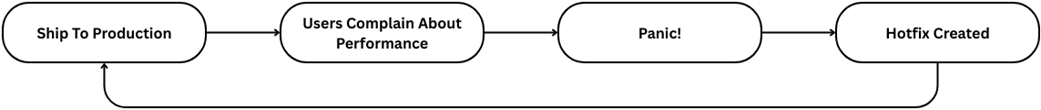
The cycle shows why complaint-driven hotfixes fail to preserve performance: each rushed patch buys time but leaves regression prevention absent. section 1.1
Dashboard system paths
A dashboard filter action can cross four system paths: user action, data fetch, execution and rendering, then the visible result. Delay compounds when filters trigger unnecessary re-renders, requests run sequentially without caching, heavy libraries render excessively, and incomplete states appear before data arrives. Improvement starts by measuring evidence, then fixing root causes, exposing performance in CI and code review, and maintaining gains through monitoring and regular review. section 1.4 section 1.6
A Fast by Default approach makes performance an ongoing team practice:
- Measure impact and set user-centered goals so slowdowns are detected before users must report them. section 1.0 section 1.6
- Build efficient architecture and code by addressing root causes along the relevant system path. section 1.4 section 1.6
- Own performance through budgets and visibility in CI and code reviews rather than assigning it to isolated audits. section 1.0 section 1.4
- Maintain gains with production monitoring, lightweight audits, and regular reviews as real-world usage and product expectations change. section 1.4 section 1.5
Speed is also a business concern. Slow experiences reduce trust and engagement; users may leave, convert less often, or switch elsewhere rather than report a performance problem. Fast systems can improve conversion and retention, reduce wasted compute and firefighting, and let engineers ship with greater confidence. section 1.2 section 1.0









