When an ensemble trains each component on a bootstrap sample, some training examples are omitted from that component. Those omitted examples form its out-of-bag (OOB) sample: an effectively held-out test set for evaluating the component and, collectively, the ensemble. section 2.2.1
Compute an OOB estimate through repeated bootstrap training:
- Draw a bootstrap sample with replacement for each base estimator; repeated examples remain in training, while omitted examples become that estimator’s OOB sample. section 2.2.1
- Predict each example using only ensemble components for which that example was out of bag. section 2.2.1
- Aggregate those predictions and calculate the resulting error or score. This uses the training data efficiently without requiring a separate validation set or cross-validation procedure. section 2.2.1
A small bootstrap sample
For 50 training examples, sample 50 indices with replacement. The resulting bootstrap sample may repeat indices such as 12, 14, and 21; the remaining indices, such as 0, 2, and 5, form the corresponding OOB sample. With scikit-learn, set oob_score=True on BaggingClassifier, fit the ensemble, and read bag_ens.oob_score_. One demonstrated OOB accuracy is 96.6%, compared with 95.2% on a held-out test set. section 2.2.1 section 2.2.3
Figure 2.3 Bootstrap sampling illustrated on a data set of six examples. By sampling with replacement, we can get a bootstrap sample size of six, containing only four unique objects but with repeats. Performing bootstrap sampling several times produces several replicates of the original data set—all of them with repeats.
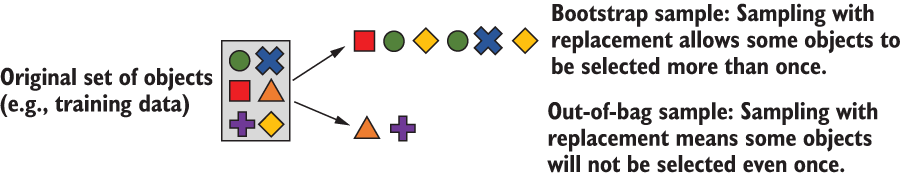
Visualize how sampling with replacement creates repeated training examples and a complementary OOB subset; repeating the process produces varied ensemble training sets. section 2.2.1
