Apache Parquet is a column-oriented file format designed for efficient storage and retrieval of structured data. In a deep-learning data pipeline, it provides an intermediate dataset representation between storage tables and framework-specific training datasets. section 2.3.1
A practical Parquet workflow assigns it a narrow interoperability role:
- Cache Delta Lake table data as Parquet files. section 2.3.1
- Use Petastorm to convert the Parquet-backed data into TensorFlow or PyTorch datasets. section 2.3.1
- Keep dataset representation separate from TensorFlow, PyTorch, and PySpark training applications. section 2.3.1
Flower image training pipeline
An image ETL pipeline writes labeled image data to a Delta Lake table; Petastorm then converts that dataset for direct PyTorch training. section 2.3.1
Figure 2.17 Petastorm converts the Delta Lake table to datasets that can be read by the PyTorch or Tensorflow framework.
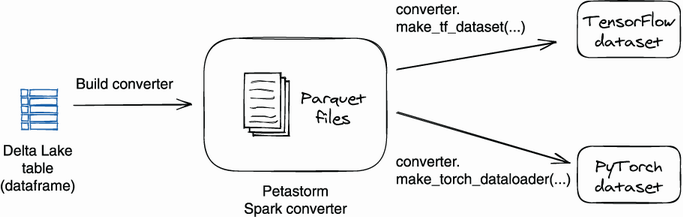
Visualizes Petastorm converting a Delta Lake table into datasets readable by PyTorch or TensorFlow. section 2.3.1








