Parquet is a column-oriented binary format for storing structured data efficiently. In an ML preprocessing workflow, converting CSV inputs to compressed Parquet makes larger tabular datasets easier to handle across pipeline components. section 7.3.2 section 7.4
A production-oriented Parquet workflow can:
- Convert ratings and movie CSV files with pandas and gzip compression. section 7.3.2
- Read Parquet data before splitting it into training, validation, and test datasets. section 7.3.2
- Store resulting files in MinIO and read them directly with PyArrow for quality checks. section 7.3.2
Movie recommender preprocessing
A Kubeflow pipeline downloads the MovieLens 25M archive, extracts ratings and movies CSV files, converts them to compressed Parquet, splits ratings into train/validation/test data, uploads the artifacts to MinIO, and verifies the stored training file with PyArrow. section 7.3.2 section 7.4
Figure 7.14 The pipeline we’ll build out in this section
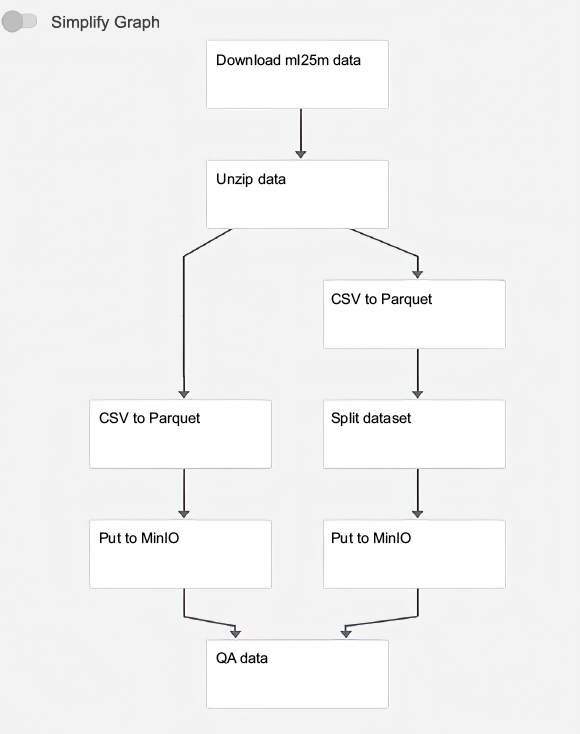
Use the pipeline diagram to trace Parquet conversion from extracted CSV artifacts through dataset splitting, storage, and quality assurance. section 7.3.2








