An image patch is a small, localized portion of an image treated as an individual visual input unit. Convolutional layers extract patches from feature maps and apply the same transformation at many locations, helping models learn patterns such as edges and textures before combining them into larger visual concepts. section 8.1.1
Patches can be used in several closely related ways:
- Convolution uses typically 3 × 3 or 5 × 5 patches, moving them across the height and width of a feature map. section 8.1.1
- A patch includes the feature map’s channel depth: an RGB 3 × 3 patch contains values from all three color channels. section 8.1.1
- Vision Transformers split an image into a one-dimensional sequence of patches, flatten each patch into a vector, and process the resulting sequence. section 9.6
- A multimodal image encoder can turn 256 patches into vectors that act like soft tokens alongside text tokens. section 16.4.2
Figure 8.5 Valid locations of 3 × 3 patches in a 5 × 5 input feature map
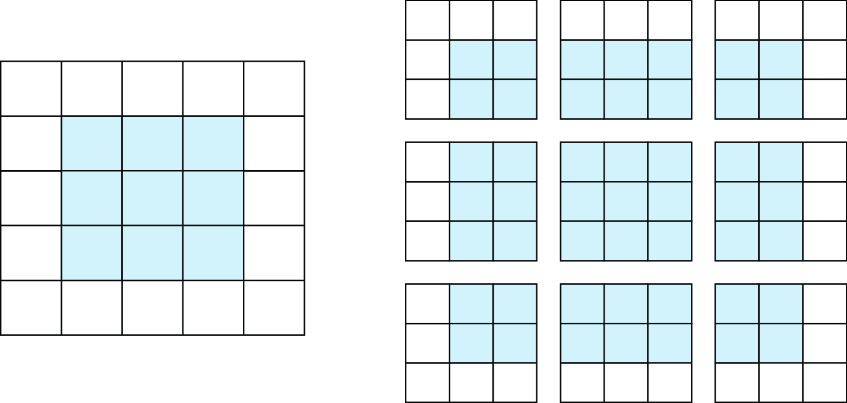
Shows where 3 × 3 patches can be placed within a 5 × 5 input feature map. section 8.1.1




