Preference tuning, also called preference fine-tuning (PreFT), is the post-training stage that adjusts a language model toward outputs people prefer. It follows instruction fine-tuning, which establishes instruction-following format and basic behavior, and targets subtler qualities of language that are difficult to specify as an ordinary loss function. RLHF is the established core of this area, while newer direct and reward-based approaches broaden it beyond a single recipe. section 1.1 section 2.3
The central difficulty is that desired human behavior cannot be precisely written as a reward or loss function. Preference data therefore acts as a proxy signal: labeled comparisons help a model match desired behaviors and avoid unwanted ones. This makes data collection a technical and operational part of optimization, not merely an annotation step; collection is costly, complex, and often needs generations from the model currently being trained. section 11.0 section 11.2.5
Common formulations and placement in a training pipeline include:
- RLHF: train a supervised model, build a reward model from preference data, then optimize the model with reinforcement learning. section 1.1
- Direct preference optimization (DPO): take gradient steps directly on pairwise preference data, pursuing the RLHF optimization problem with fewer moving parts. section 1.5
- Process rewards and execution feedback: extend preference-oriented training to intermediate reasoning steps and feedback from code, math, or other online reasoning settings. section 2.3
- Tool-use preference optimization: compare trajectories to improve the decision of whether to call a tool or answer directly; use environment-feedback RL for multistep task success. section 13.5 section 13.6
Choosing whether to call a tool
For a tool-use prompt, supervised fine-tuning can teach the syntax and selection of a function call. Preference optimization over complete trajectories can then favor an appropriate tool call over answering directly. When several tool actions are required, task success and constraint satisfaction provide environment feedback for reinforcement learning. section 13.5 section 13.6
Figure 1.1 A rendition of the early three-stage RLHF process: training via supervised fine-tuning (SFT; chapter 4), building a reward model (RM, chapter 5), and then optimizing with RL (chapter 6).
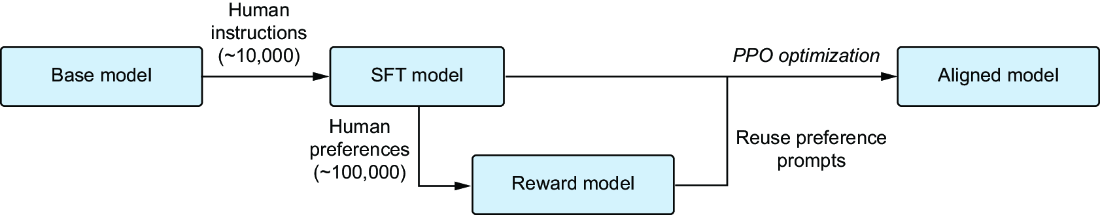
The three-stage RLHF diagram situates preference tuning between instruction-oriented supervised fine-tuning and reinforcement-learning optimization through a learned reward model. section 1.1
In open post-training, DPO became influential because it simplified the optimization path, but strong results still depended on practical choices such as a lower learning rate and suitable data. Preference tuning is not a complete post-training recipe: instruction fine-tuning, RLHF or direct methods, prompt design, and newer verifiable-reward training can be combined in different orders for different capabilities. section 1.5 section 1.1

