A prior distribution p(θ) represents initial probability beliefs about model parameters or latent variables before observing current data. Bayesian inference combines it with the likelihood p(x|θ) to obtain the posterior p(θ|x), with the posterior proportional to their product. section 1.4
A prior can be characterized by its information, form, and computational role:
- Use a noninformative prior, such as a uniform distribution, when assigning equal initial belief across possible states. section 1.4
- Use an informative prior to encode domain experience or information from an earlier experiment. section 1.4 section 2.1.1
- Prefer a conjugate prior when its form is preserved by the posterior, because the update can then have a closed form. section 1.4 section 2.1.1
- Account for the normalizing constant p(x) = ∫p(x|θ)p(θ)dθ, which can be difficult to compute in high-dimensional parameter spaces. section 1.4
Beta prior for coin flips
Let θ denote the probability that a coin lands heads. If an earlier experiment produced a heads and b tails, represent prior information with a Beta distribution. After observing N1 heads and N0 tails, combine the likelihood with the Beta prior; the posterior remains Beta and updates the prior counts with the observed data. section 2.1.1
Figure 1.4 A Bayes engine showing the transformation of a prior to a posterior as more data is observed
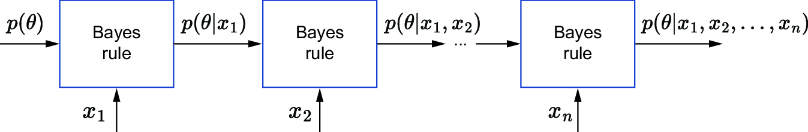
Trace the transformation from a prior to a posterior as additional data is observed. section 1.4







