Production data is generated in the environment where a deployed model is used. Training data should represent this environment; otherwise, a model that performs well on tests may fail on real inputs. section 6.1.2
To keep data aligned with deployment:
- Collect and annotate examples from the intended environment when possible. If that is not possible, understand and actively correct differences between training and production data. section 6.1.2
- After deployment, monitor new data and model behavior, audit predictions against fresh annotations when possible, and keep collecting difficult examples for future training. section 6.3.4 section 6.3.3
When training images do not match deployment
A dish-recognition app trained on polished food-sharing photos may fail on casual mobile pictures taken in restaurants. The test score can be high while deployed predictions are often wrong. section 6.1.2
“DEWEY DEFEATS TRUMAN”: a famous example of sampling bias
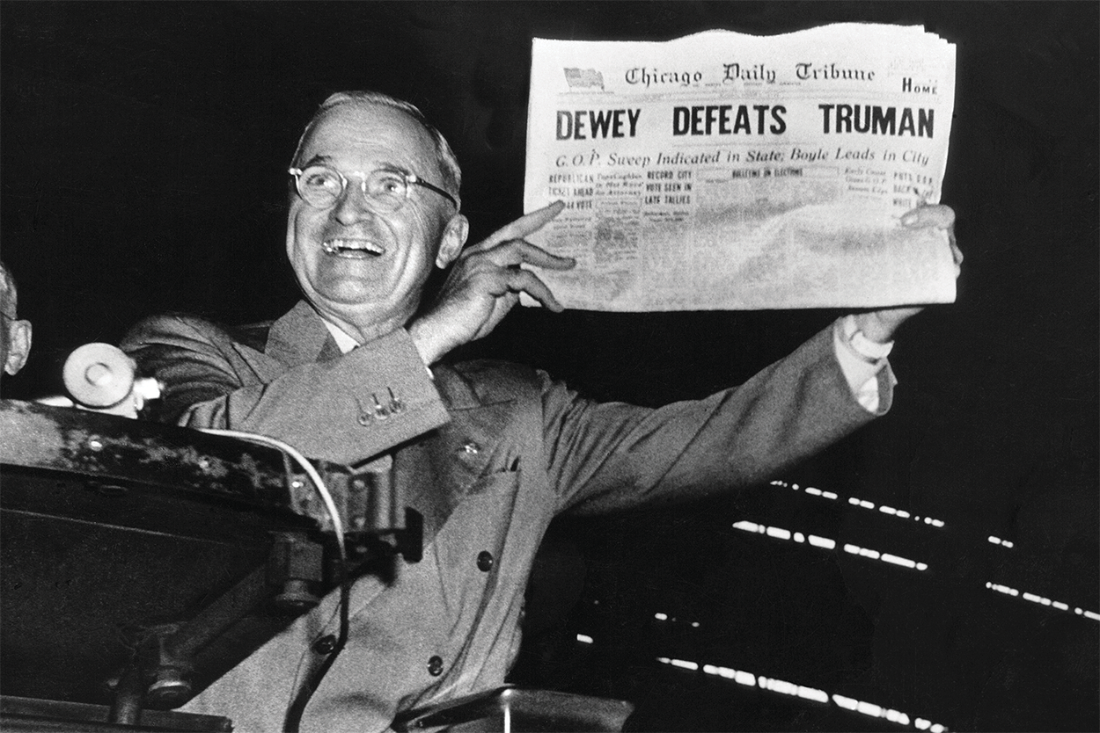
A visual example of sampling bias reinforces why collected data may not represent the population a model encounters. section 6.1.2


