Production data is the real operational input a model encounters after deployment. It is the reference point for estimating future performance: training, validation, and test data should resemble it closely enough to measure generalization honestly. section 6.1.2 section 5.2.1
When a strong test score fails in production
A dish-recognition app trained on polished, well-lit food photographs can exceed 90% test accuracy yet fail on mobile photographs taken in ordinary restaurants. The problem is not necessarily the model: the training data does not represent the production inputs. Collecting and annotating images from the deployment environment gives the model a more relevant basis for learning. section 6.1.2
Use production data as a practical check on dataset and evaluation decisions:
- Collect data directly from the environment where the model will operate whenever possible. section 6.1.2
- Match the population and input conditions expected after deployment, rather than substituting superficially similar sources. section 6.1.2
- Make the test set as similar as possible to production data, and preserve it for final evaluation after model tuning. section 5.2.1
- Check validation-set representativity and avoid redundant samples between training and validation sets. section 6.2.2
“DEWEY DEFEATS TRUMAN”: a famous example of sampling bias
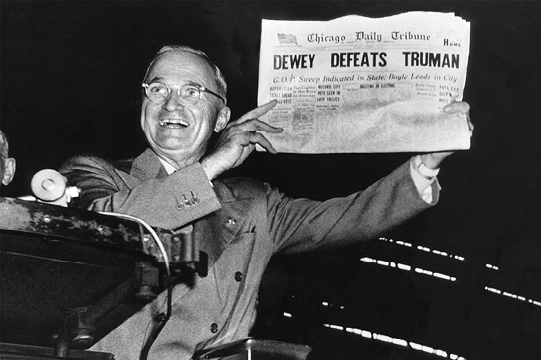
Use the sampling-bias example to see how a dataset can produce confident results while misrepresenting the inputs encountered in practice. section 6.1.2

