A tensor is a structured numerical representation used to carry model data and intermediate states. In Fusion-in-Decoder, the encoder returns a tensor shaped [N, sequence_length, hidden], containing one representation for each independently encoded question–passage sequence. section 5.2
Stacking and fusion
For N retrieved passages, the encoder produces N separate tensor representations. Fusion reshapes them into one sequence of length N × sequence_length; it does not sum or otherwise merge their values. The decoder then reads this long representation through cross-attention. section 5.2
Figure 5.2 The FiD architecture: Independent Encoding, Fused Decoding.
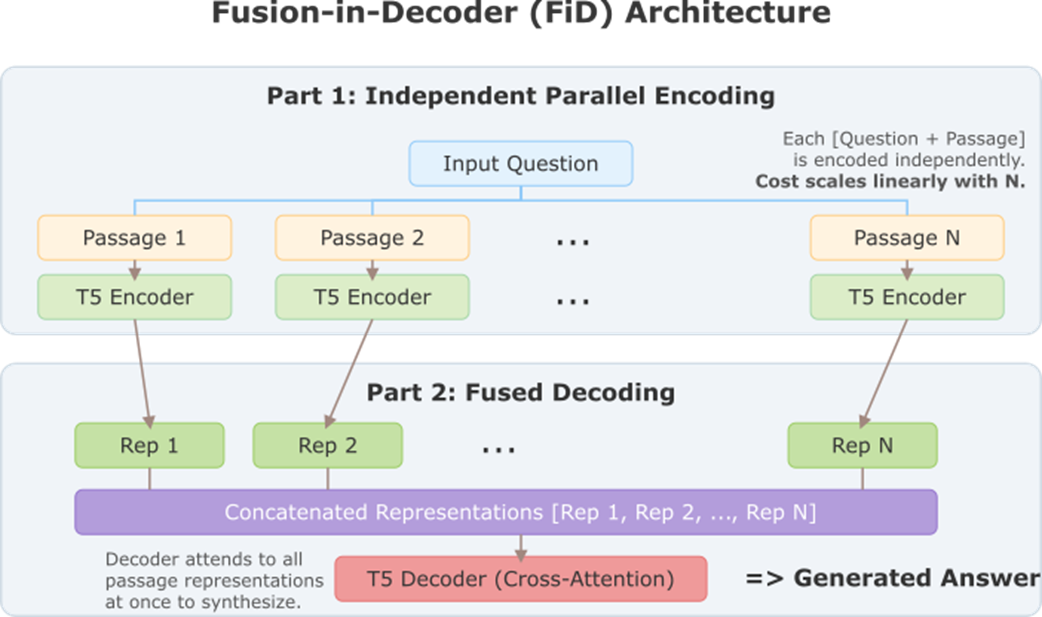
Use the architecture figure to trace how separate encoder tensors become one decoder-visible representation. section 5.2









