Random subspaces builds an ensemble by giving each component model a randomly selected subset of features. Like asking several analysts to inspect different evidence, this creates diverse predictions that can be aggregated. Unlike random forests, which sample features inside randomized tree learning, random subspaces selects features once before training each base estimator. section 2.4.2 section 2.0
A practical workflow is:
- Choose a base learner and the number of component estimators. section 2.4.2
- For each estimator, randomly select a feature subset, with or without replacement. section 2.4.2
- Train the learner using its selected features, then combine the component predictions. section 2.4.2 section 2.6
- Use smaller feature subsets when high dimensionality makes individual models expensive, such as with image or text data. section 2.4.2
Scikit-learn configuration
A BaggingClassifier with SVC as its base estimator can implement random subspaces by setting max_features below all features while leaving training-example sampling disabled: max_samples=1.0, bootstrap=False, max_features=0.5, and bootstrap_features=True. Sampling both examples and features instead produces random patches. section 2.4.2
Figure 2.9 Bagging compared to random subspaces and random patches. The unshaded rows and columns represent training examples and features, respectively, that have been left out.
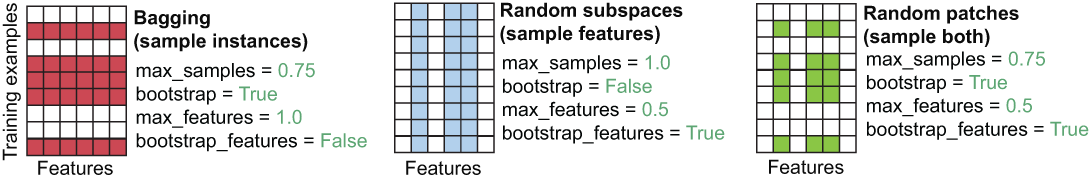
Compare which training examples and feature columns each ensemble member receives; omitted columns make random-subspace sampling visually distinct from bagging and random patches. section 2.4.2


