A data stream is a continuous or unbounded sequence of records processed as they become available. In an enterprise system, services can exchange streams near real time instead of waiting for batch processing. section 1.0 section 12.0
A stream may represent related records that should remain together. Kafka divides large streams into partitions for parallel processing, while offsets record how far a consumer has read. section 11.1
Common representations make the same pattern visible across systems:
- A Kafka topic contains partitions, each holding an ordered portion of a stream. section 11.1
- A database table can be treated as a stream of rows, with sequential identifiers or timestamps tracking processed records. section 11.1
- A file can act as a stream whose read position is tracked by the last line or byte consumed. section 11.1
From event exchange to immediate analysis
An enterprise can exchange records between independent services through Kafka, retain those records, and process the continuous stream as it arrives. Stream processing can then produce analyses immediately rather than after a daily batch. section 1.0 section 12.0
Figure 11.2 A partitioned stream uses partitions for parallelization and offsets to remember the last read message.
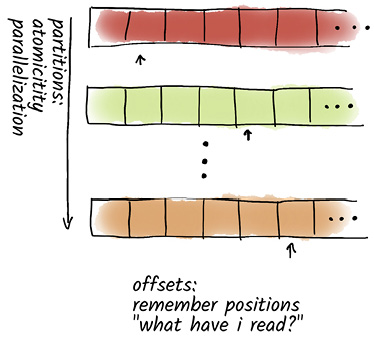
Shows how partitions support parallelization and offsets remember the last message read. section 11.1


