Reference-free evaluation assesses a RAG pipeline without expensive human-annotated ground-truth answers. RAGAS uses LLMs to evaluate pipeline components directly. section 6.5.2
RAGAS combines four complementary metrics:
- Context precision checks whether relevant retrieved chunks appear near the top of the results. section 6.5.2
- Context recall checks whether retrieval covers all relevant aspects of the query. section 6.5.2
- Faithfulness checks the generated response against the retrieved documents to detect factual errors and hallucinations. section 6.5.2
- Answer relevancy generates artificial questions from an answer and compares them with the original query. section 6.5.2
Composite RAGAS Score
Use the four metrics together to obtain a single overall measure for comparing RAG configurations and tracking improvements over time. section 6.5.2
Figure 6.7 RAGAS Core Metric extensively covers LLM Grounding and Response (Source)
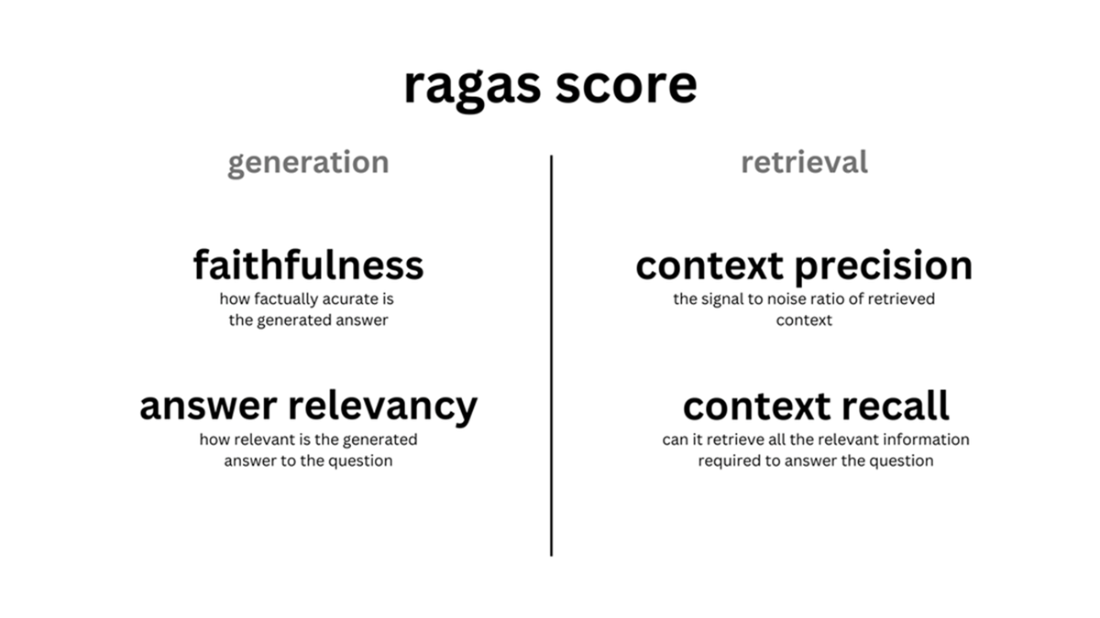
Inspect how the core metrics jointly evaluate retrieved context, LLM grounding, and generated responses. section 6.5.2



