A rectified linear unit (ReLU) returns its input when positive and returns zero otherwise: F(x) = max(0, x). Its simple, unbounded form is inexpensive to compute, though it is not centered at zero and is not differentiable at zero. section 8.2.4
ReLU is widely used in hidden layers because its low computational cost can speed network training. In convolutional neural networks, it adds nonlinearity so the model can represent complex patterns after convolution extracts features. section 8.2.4 section 8.6.1
(8.3)
F(x) = max (0, x)
Use the equation to inspect ReLU’s piecewise behavior: negative inputs map to zero, while positive inputs pass through unchanged. section 8.2.4
Figure 8.7 A ReLU function. It is one of the favored activation functions in the hidden layers of a neural network. A ReLU is simple to use and less expensive to train.
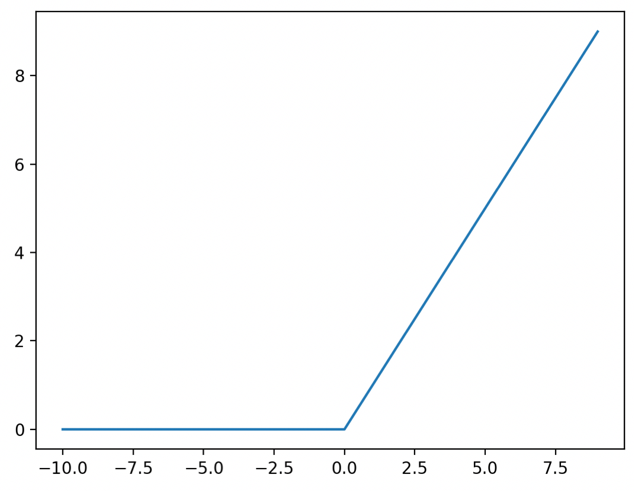
Use the graph to see ReLU’s flat nonpositive region and rising positive region, as well as its role in hidden layers. section 8.2.4











