Stochastic gradient descent (SGD) trains a model by repeatedly adjusting parameters in the direction indicated by estimated gradients. Individual examples or small batches can supply those estimates, while the learning rate controls update size. section 4.1.1
A practical SGD training loop:
- Calculate the loss and gradients for the current model parameters. section 4.1.1
- Update each weight using its gradient multiplied by the learning rate. section 4.1.1
- Repeat updates until the loss reaches a minimum or stabilizes. section 4.1.1
Choosing the learning rate
A learning rate set too high can overshoot the optimum or prevent convergence; one set too low can make training slow or stall in local minima. section 4.1.1
Figure 4.6 Steps in the training of a deep learning model using gradient descent.
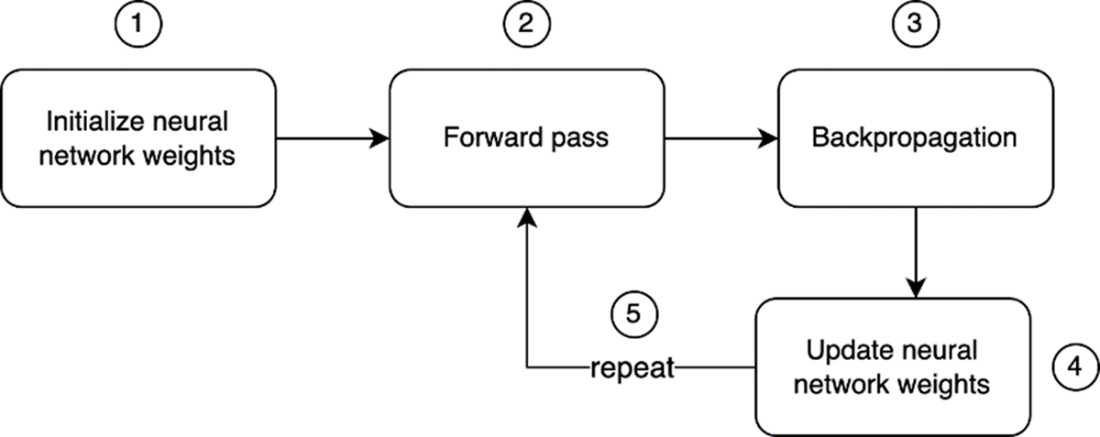
Shows the training steps of a deep learning model using gradient descent. section 4.1.1
















