A sidecar process runs beside a primary application container, encapsulating adaptation, proxying, and initialization requirements without changing the primary service. section 7.2.7 section 7.4.5
In model serving, the sidecar downloads model files into shared storage, registers the model, translates requests, and forwards them to a black-box inference server. section 7.2.7 section 7.4.5
A sidecar supports deployment by:
- Keeping the public prediction API and external model storage unchanged while replacing or integrating the backend. section 7.4.5
- Sharing a volume across server pods to provide a common model repository and reduce repeated downloads and network bandwidth. section 7.2.7 section 7.4.5
- Letting a load balancer distribute prediction requests across pods without exposing server-specific registration requirements to callers. section 7.2.7
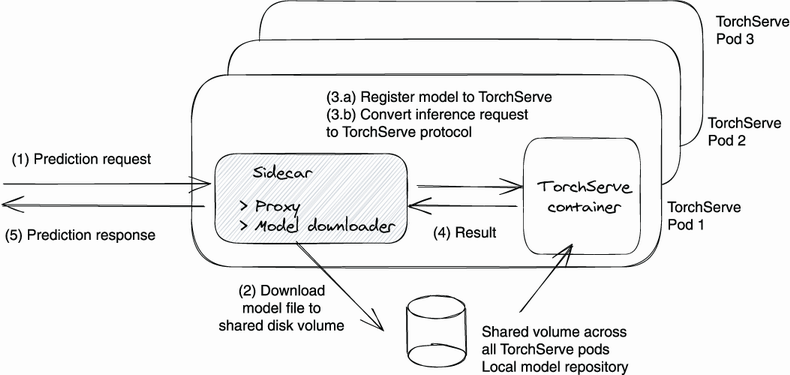
Use the architecture diagram to trace the proxy, TorchServe container, shared model store, and load-balanced pod workflow. section 7.2.7










