Singular value decomposition (SVD) factorizes a matrix W into U, S, and V: orthogonal matrices U and V plus a diagonal matrix S. Multiplying the factors reconstructs W exactly, while the largest singular-value dimensions capture the directions selected for reduction. section 4.3.2
For text analysis, SVD transforms bag-of-words or TF–IDF document vectors into lower-dimensional topic vectors. Truncated SVD keeps only p dimensions, making large sparse matrices more manageable and supporting latent semantic analysis and semantic search. section 4.11 section 4.3.2
A practical SVD workflow for semantic analysis is:
- Represent documents as a bag-of-words or TF–IDF matrix. section 4.11
- Apply truncated SVD and choose the number p of topic dimensions to retain. section 4.3.2
- Compare document distances or similarities in the reduced topic-vector space. section 4.6
- Use a hyperparameter table to compare pipelines and models before deploying semantic search. section 4.11
TruncatedSVD or PCA?
Both scikit-learn methods use SVD-based matrix decomposition, but PCA centers the input while TruncatedSVD does not. Centering a sparse TF–IDF matrix can make it dense, increasing memory use and slowing computation. To compare equivalent results, center the data explicitly before TruncatedSVD: `tfidf_docs = tfidf_docs - tfidf_docs.mean()`. section 4.4.2
SVD-based reduction preserves large distances better than fine local structure because it maximizes overall variance. Check whether documents with similar subject matter remain close, and choose a distance measure suited to the NLP pipeline. section 4.6
Equation 4.2 Truncated SVD
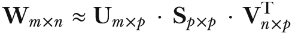
Use the truncated-SVD equation to relate the original matrix dimensions m and n to the retained topic dimensions p. section 4.3.2





