Softmax converts rescaled next-token logits into probability scores so sampling can select the next token from a normalized distribution. section 4.4.3
The inference workflow uses softmax to:
- Normalize each logit to a value from 0 to 1, with all probability values summing to 1. section 4.4.3
- Reflect temperature effects: lower temperature concentrates probability, while higher temperature spreads it across more tokens. section 4.4.3
- Pass the resulting distribution to next-token sampling, such as torch.multinomial. section 4.4.3
A temperature-scaled distribution
Applying torch.softmax to logits scaled with temperature 5.0 gives the token " Berlin" the highest probability in the selected vocabulary range, but only 0.0003. At temperature 0.5, its probability rises to 0.3398, while competing probabilities move closer to zero. section 4.4.3
Figure 4.10 Overview of the sampling process for generating tokens. Here, we focus on steps 3.3 and 3.4, where the next-token scores are converted into a probability distribution. The next token will be sampled based on that distribution.
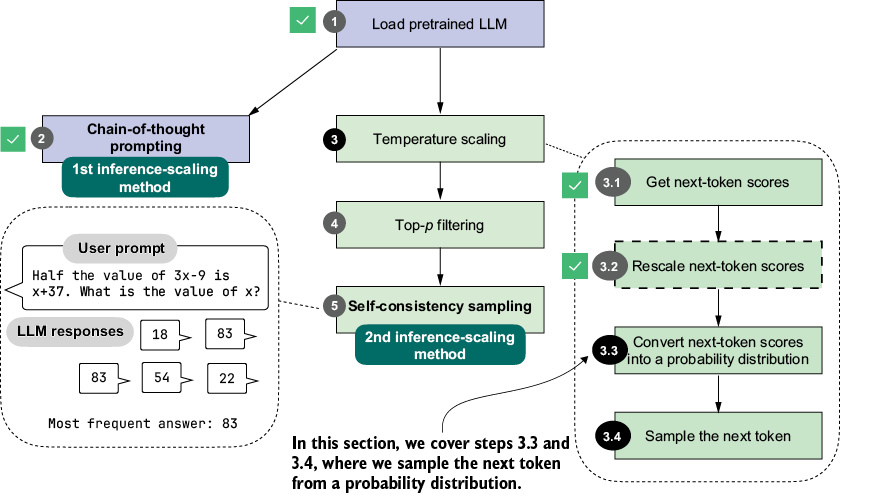
Follow the sampling workflow from rescaled logits through softmax probabilities to next-token selection. section 4.4.3
















