Softmax turns K real-valued scores into nonnegative values that sum to one. For scores a₁,…,aₖ, the output for class k is exp(aₖ) divided by the sum of exp(aⱼ) over all classes j. The resulting vector can be interpreted as a distribution over classes. section 5.4
In probabilistic classification, the target is p(Cₖ|x): the probability of class Cₖ given input x. Bayes’ rule supplies a score aₖ = ln[p(x|Cₖ)p(Cₖ)] for each class. Exponentiating and normalizing those scores gives the multiclass posterior. This connects softmax to both the class-conditional density and the class prior. section 5.4
(5.21)
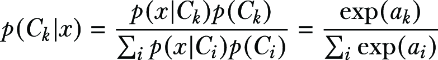
The multiclass posterior equation shows how the class scores are normalized. section 5.4
The same normalization serves different outputs:
- A softmax classifier follows the dense layer of a LeNet-style CNN for MNIST handwritten-digit classification. section 10.2.1
- Softmax activations make the mixture weights of a Gaussian mixture density network sum to one; exponential activations separately keep its variances positive. section 11.2.1
Temperature softmax is a further practice question: examine how changing its temperature parameter T changes the output. The binary logistic-regression implementation is not, by itself, an implementation of a multiclass softmax classifier. section 7.7 section 5.4
















