Apache Spark is a distributed processing engine for batch, micro-batch, streaming, and analytical workloads. In an Iceberg lakehouse, it extracts data, performs transformations, and writes governed tables to object storage through a catalog. section 6.4.1 section 3.6
Spark separates processing from storage and connects to Iceberg through Spark SQL and DataFrame APIs. This supports partitioned writes, compaction, overwrites, merges, and streaming ingestion while leaving table data and metadata in the configured storage and catalog layers. section 6.4.1 section 3.3
Use Spark when the ingestion design requires:
- Large-scale batch ETL and scheduled transformations. section 6.4.1
- Partitioned overwrites that replace affected partitions while preserving the rest of a table. section 6.4.1
- Merge operations for upserts, slowly changing dimensions, late-arriving data, and reconciliation. section 6.4.1
- Structured Streaming micro-batches written to Iceberg with checkpointing and configured exactly-once semantics. section 6.4.1
- Complex cleansing, joins, masking, filtering, and derived fields before storage, accepting greater tuning and testing demands. section 6.5.3
PostgreSQL to Iceberg
A local Docker Compose environment uses PostgreSQL as an operational source, Spark as the ingestion engine, MinIO as S3-compatible storage, and Nessie as the Iceberg catalog. A PySpark job reads sales data from PostgreSQL, transforms it, writes Iceberg tables to MinIO, and updates Nessie metadata; Dremio and Superset consume the resulting datasets. section 3.2.3 section 3.2
Figure 3.1 A hands-on lakehouse workflow, from sales data to BI dashboards
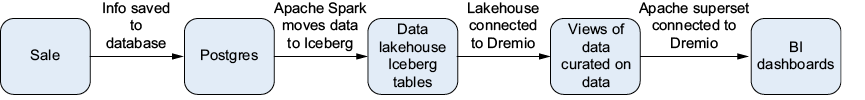
Trace the end-to-end path from operational sales data through Spark and Iceberg to analytical views and BI dashboards. section 3.1
conf = (
    pyspark.SparkConf()
        .setAppName('Iceberg Ingestion')
        .set('spark.jars.packages',
             'org.postgresql:postgresql:42.7.3,'
             'org.apache.iceberg:iceberg-spark-runtime-3.5_2.12:1.5.0,'
             'org.projectnessie.nessie-integrations:nessie-spark-extensions-3.5_2.12:0.77.1,'
             'software.amazon.awssdk:bundle:2.24.8,'
             'software.amazon.awssdk:url-connection-client:2.24.8')
        .set('spark.sql.extensions',
             'org.apache.iceberg.spark.extensions.IcebergSparkSessionExtensions,'
             'org.projectnessie.spark.extensions.NessieSparkSessionExtensions')
        .set('spark.sql.catalog.nessie', 'org.apache.iceberg.spark.SparkCatalog')
        .set('spark.sql.catalog.nessie.uri', CATALOG_URI)
        .set('spark.sql.catalog.nessie.ref', 'main')
        .set('spark.sql.catalog.nessie.authentication.type', 'NONE')
        .set('spark.sql.catalog.nessie.catalog-impl', 'org.apache.iceberg.nessie.NessieCatalog')
        .set('spark.sql.catalog.nessie.s3.endpoint', STORAGE_URI)
        .set('spark.sql.catalog.nessie.warehouse', WAREHOUSE)
        .set('spark.sql.catalog.nessie.io-impl', 'org.apache.iceberg.aws.s3.S3FileIO')
) #1
Inspect the Spark configuration pattern for loading PostgreSQL, Iceberg, Nessie, and S3 client dependencies into an ingestion session. section 3.3.3




