Speech recognition, also called automatic speech recognition (ASR), turns spoken audio into written text. It lets you speak into a microphone and use the resulting words as input to a chat application. The task is harder than it sounds: accents, speaking pace, background noise, and words that run together can all make speech ambiguous. section 9.1 section 1.2
Whisper is a speech-recognition model that can run offline. It converts audio into a spectrogram, a representation of sound frequencies over time. An encoder processes that representation; a decoder uses its output, along with tokens specifying the language and task, to generate a transcript. MLX Whisper adapts Whisper for Apple silicon so transcription can stay on your Mac. section 9.1 section 9.11
Figure 9.1 Whisper’s encoder-decoder architecture. Audio is converted into a spectrogram, which the encoder processes. The decoder processes the encoder’s output together with control tokens to generate a transcript.
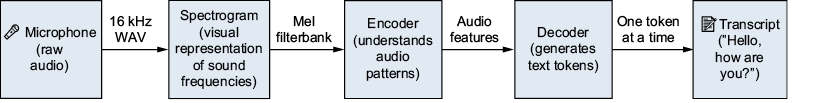
Follow the diagram from audio to spectrogram, then through the encoder and decoder to the transcript. section 9.1
Turn a recording into chat input
Record with a microphone, then give MLX Whisper a file path: `result = mlx_whisper.transcribe(path, path_or_hf_repo=model)`. The recognized words are in `result["text"]`; those words can be sent to an Ollama language model just like typed input. Microphone recordings prepared for Whisper must be mono and 16 kHz. If a browser supplies in-memory WAV bytes, save them to a temporary file for transcription and delete that file in a `finally` block. section 9.11 section 10.9
Model size is a practical trade-off. Start with `small` when memory is limited, try `medium` with more unified memory, and choose `large-v3` only if its accuracy benefit warrants the extra memory and latency. section 9.11





