Speech recognition converts spoken language in audio into usable text or identified speech. Speech-to-text conversion can turn voice commands and recorded customer calls into large text datasets for analysis and service improvement. section 7.2
Deep learning enables automatic speech recognition through sophisticated neural networks. Named applications include Siri, Alexa, Translator, and Baidu. section 8.1.1
A deep-learning treatment connects speech recognition with:
- Layered representation learning, where successive restricted Boltzmann machines learn increasingly abstract features. section 8.9.1
- Supervised fine-tuning with labeled data and backpropagation to reduce prediction error after unsupervised pretraining. section 8.9.1
- Practical constraints such as computational cost, hyperparameter tuning, labeled-data requirements, and vanishing gradients. section 8.9.1
From call recording to text
A recorded call-center conversation can be processed with speech-to-text conversion, producing text that organizations can use as a source of customer information. section 7.2
Figure 7.1 Unstructured data can be text, images, audio, or video. We deal with text data in this chapter. This list is not exhaustive.
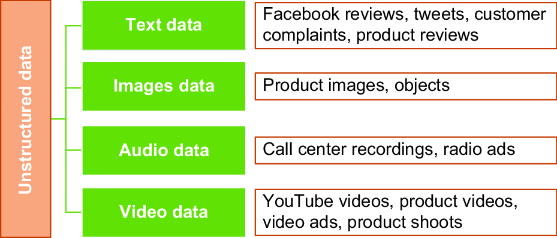
Use the figure to situate speech audio among other unstructured data types and distinguish it from the text produced by transcription. section 7.2





