A teacher model is a larger language model whose outputs supervise a smaller student during model distillation. For reasoning tasks, those outputs can include a final answer and the intermediate reasoning trace. section 8.1
The teacher supplies training targets rather than serving as the deployable model. Its generated traces let a smaller model learn reasoning behavior at lower development, inference, and hardware cost. section 8.1 section 8.9
Distillation uses teacher information in two principal ways:
- Hard distillation trains the student on teacher-generated text, treating the teacher's tokens as targets; this is usually more practical because text is cheaper to store and teacher logits may be unavailable. section 8.1 section 8.11
- Soft distillation trains the student to match the teacher's vocabulary probability distribution by minimizing KL divergence. section 8.1
Reasoning-model distillation
DeepSeek-R1, with 671 billion parameters, served as the teacher for smaller distilled variants. A practical setup used DeepSeek-R1 as teacher and Qwen3 0.6B as student, training on teacher reasoning traces and final answers from MATH problems. section 8.1 section 8.11
Figure 8.2 Hard distillation trains the student on teacher-generated tokens; soft distillation trains the student on the teacher’s full output distribution.
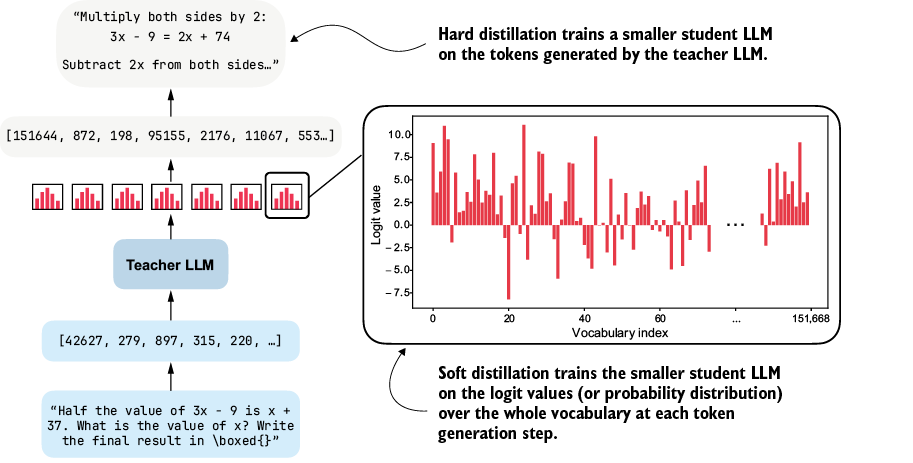
Compare hard distillation from teacher-generated tokens with soft distillation from the teacher's full output distribution. section 8.1

