Transfer learning adapts a model pre-trained on one task as the starting point for a related but different task. It can improve performance while reducing training time. section 2.1
Within Transformer-based NLP systems, pre-training on vast amounts of unlabeled text supplies reusable knowledge before task-specific training. This complements parallel processing and self-attention, which capture long-range relationships. section 2.1
Transformer pre-training
A model pre-trained on one language task becomes the starting point for a different, related task instead of beginning training from scratch. section 2.1
Figure 2.1 The strength of the transformer model is in its ability to understand the significance and context of every word in a sentence, unlike RNNs which primarily assess the connection of a word with its immediate neighbor.
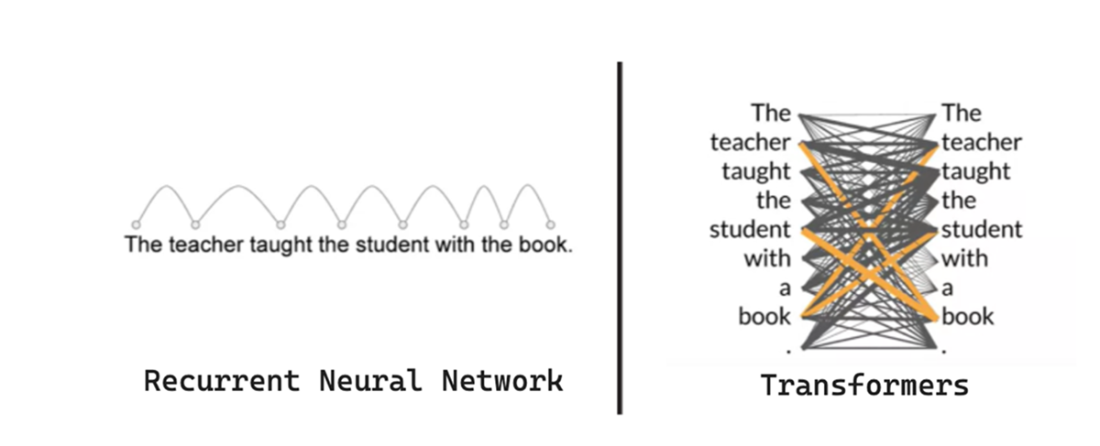
Use the figure to connect Transformer self-attention with its ability to capture word significance, context, and long-range relationships. section 2.1















