Transfer learning reuses patterns or weights learned from a generic task to improve a different task, avoiding training a separate model from scratch. section 1.2 section 5.3
A practical transfer-learning pipeline typically works as follows:
- Pretrain a language model on a generic task, such as predicting randomly masked tokens, using a large text corpus. section 1.2 section 5.3
- Reuse the resulting model or its learned weights for a specific task, such as relation extraction from domain text. section 1.2 section 5.3
- Customize the model with prompting or fine-tuning when the generic capabilities are insufficient, while preparing task-specific data as needed. section 5.3 section 5.3.4
Knowledge-graph construction
A pretrained Transformer-based LLM can transfer linguistic patterns learned from masked-token prediction to named-entity recognition and relation extraction, producing structured knowledge from unstructured text with less human-labeled data. section 5.3 section 5.3.4
Figure 1.2 In transfer learning, a model (or part of it) trained on a specific task is used as part of the training and predictions for another task.
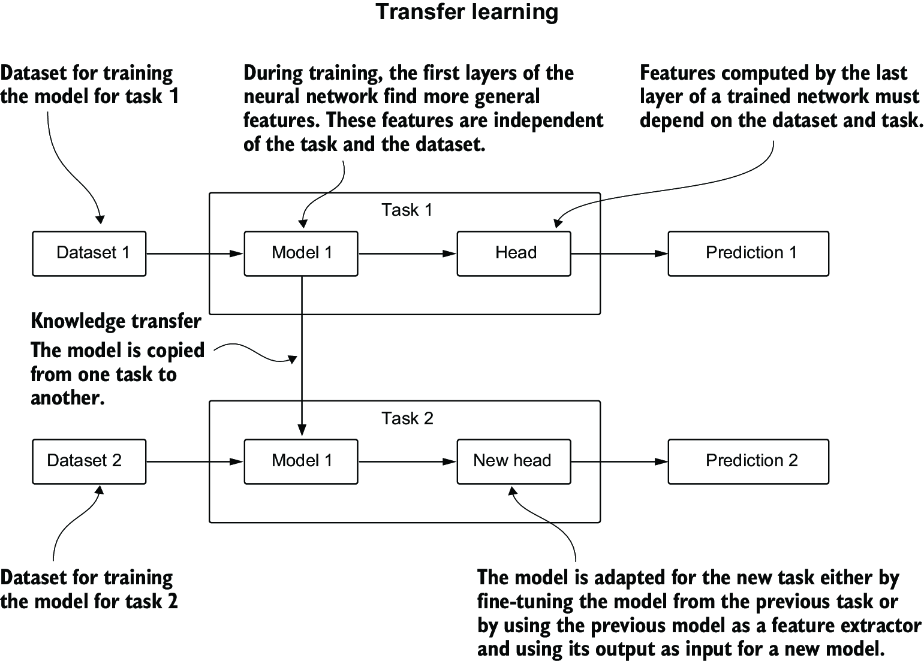
Use the figure to compare the originating task, transferred model component, and target task or prediction. section 1.2










