A value is a projected representation used to produce attention’s output. In self-attention, the input embedding passes through a neural layer with weights W_V; attention weights determine how the resulting values are combined. section 9.1.1
Library search
In a library-search analogy, book titles and descriptions act as keys, while the recommended books act as values. Query-key similarity determines which results receive higher attention. section 1.3.1
Figure 9.1 A diagram of the self-attention mechanism. To calculate attention, the input embedding X is first passed through three neural layers with weights, WQ, WK, and WV, respectively. The outputs are query Q, key K, and value V. The scaled attention score is the product of Q and K divided by the square root of the dimension of K, dk. We apply the softmax function on the scaled attention score to obtain the attention weight. The attention is the product of the attention weight and value V.
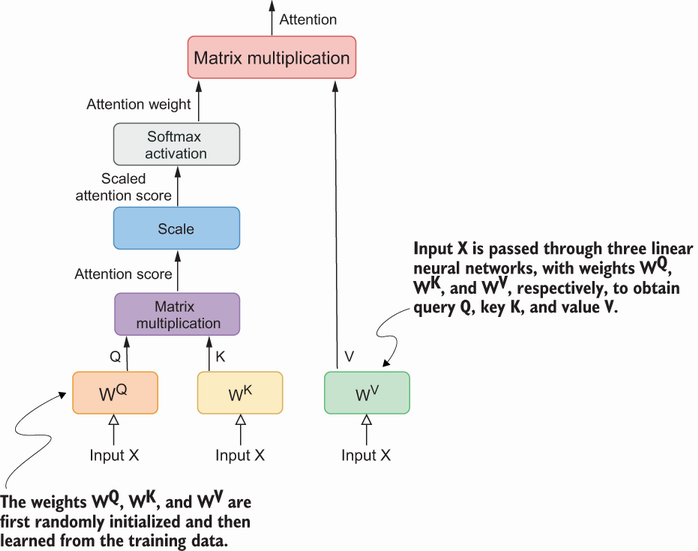
Follow the diagram from input embedding X through the value projection to the weighted attention output. section 9.1.1







