A tokenizer’s vocabulary is the finite inventory of units a model can represent. Its size and granularity shape how text is split: common patterns may have their own tokens, while rare or new words can be assembled from smaller units. section 2.4.3 section 2.4.2
Tokenization strategies make different trade-offs in vocabulary size and sequence length:
- Word-level units can produce a very large vocabulary as inflections, names, and rare terms accumulate. section 2.4.2
- Character-level units keep the vocabulary small but turn even short sentences into longer token sequences. section 2.4.2
- Subword units balance these extremes, letting known fragments represent unfamiliar words. section 2.4.2
Byte-pair encoding builds a subword vocabulary by repeatedly merging frequent adjacent symbols until it reaches a target size. Common patterns become compact tokens, while rare words can remain split into smaller pieces. WordPiece changes the merge criterion to favor units that represent the corpus more effectively. section 2.4.3 section 2.4.4
One word, several tokens
A subword tokenizer can represent “playfulness” as [“play”, “ful”, “ness”], even if the whole word was not previously encountered. section 2.4.2
Figure 2.5 Starting with characters, byte-pair encoding identifies the most frequent adjacent pairs in the corpus and merges them step by step. These merges gradually create subword units that let the model represent both common and rare words efficiently.
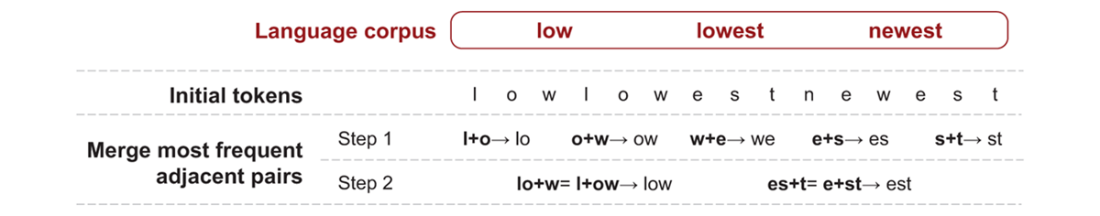
The figure traces how repeated BPE merges turn character sequences into subword units. section 2.4.3
















