Adam is an adaptive optimization algorithm that combines momentum-like averaging of gradients with RMSProp-style per-parameter learning-rate adaptation. It updates neural-network weights and biases while minimizing a loss. section 9.2.9 section 9.0
Adam maintains two state vectors during optimization:
- A first state vector forms a weighted average of past gradients, preserving momentum while improving the averaging scheme. section 9.2.9
- A second state vector tracks gradient magnitudes for RMSProp-like adaptation, reducing learning rates along dimensions with large gradients. section 9.2.9
- Bias correction replaces the early, biased state estimates with corrected quantities, improving updates at small iteration counts. section 9.2.9
PyTorch configuration
A typical Adam optimizer is created with a learning rate of 0.001 and beta values of (0.9, 0.999): optim.Adam([params], lr=0.001, betas=(0.9, 0.999)). section 9.2.9
Equation 9.16
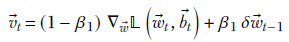
Use the equation sequence to inspect Adam's first state-vector update and connect its weighted-average behavior to momentum. section 9.2.9
Listing 9.12 PyTorch code for various optimizers
from torch import optim

sgd_optimizer = optim.SGD([params], lr=0.01)                   #1

sgd_momentum_optimizer = optim.SGD([params], lr=0.01,
                                    momentum=0.9)              #2

sgd_nesterov_momentum_optimizer = optim.SGD([params], lr=0.01, #3
                                    momentum=0.9, nesterov=True)

adagrad_optimizer = optim.Adagrad([params], lr=0.001)

rms_prop_optimizer = RMSprop([params], lr=1e-2,                #4
                       alpha=0.99)

adam_optimizer = optim.Adam([params], lr=0.001,
                       betas=(0.9, 0.999))
Compare Adam's PyTorch construction with implementations of SGD, momentum, Nesterov momentum, AdaGrad, and RMSProp. section 9.2.9






