A decoder-only transformer consists of N identical decoder layers and generates sequences autoregressively. Given a prompt, it extracts semantic meaning and predicts the most likely next token. Unlike an encoder-only transformer, which produces continuous representations, it is designed for generation rather than representation alone. section 2.1.2
Trace generation as a repeated next-token prediction loop:
- Start with a prompt or previously generated tokens. section 2.1.2
- Process the sequence through repeated decoder layers. section 2.1.2
- Predict the next token using all previously predicted tokens, then append it to the sequence. section 2.1.2
- Continue until the required sequence is complete; translation decoders use EOS to signal termination. section 2.1.2
Generating image tokens
In min-DALL-E, a pretrained BART encoder converts text into embeddings, a decoder-only transformer predicts image tokens autoregressively, and a pretrained VQGAN decoder reconstructs those tokens as visual content. Discrete image tokens make the prediction space finite and align image generation with language modeling. section 12.1.2
Figure 12.3 The image generation process in min-DALL-E to generate an image from a text prompt
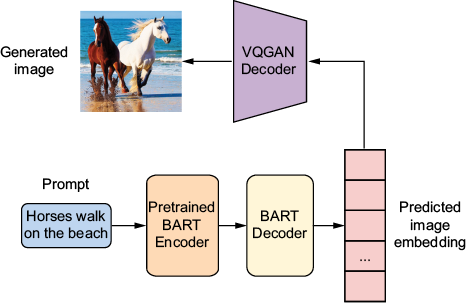
Follow the complete min-DALL-E inference path from a text prompt through image-token generation to reconstructed visual content. section 12.1.2







