A decoder-only transformer generates text from left to right, conditioning each token on those before it through masked self-attention. Introduced in 2018, it handles long input sequences better than the original Transformer and scales more easily than encoder-decoder counterparts. section 6.1.1
Scaling experiments compared decoder-only transformers with other architectures and found advantages in maintaining performance across long contexts and computational efficiency at scale. The results also showed that scaling curves were not unique to one architecture. section 6.1.1 section 6.1.5
Directional knowledge
GPT-4 can identify Tom Cruise’s mother when asked about him, yet fail to retrieve Tom Cruise when prompted with her name. This illustrates how left-to-right prediction can make reversing a relation brittle. section 7.5.2
Figure 7.7 BERT is deeply bidirectional, OpenAI’s GPT is unidirectional, and ELMo is shallowly bidirectional.
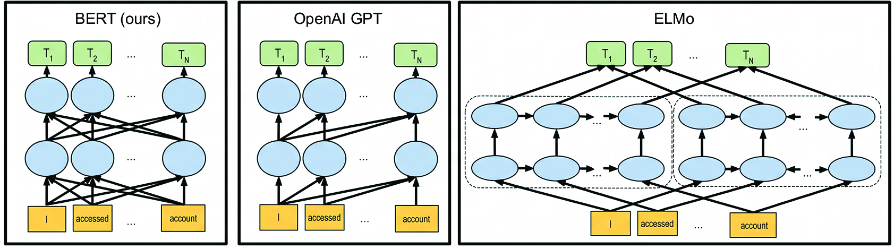
Compare the directional context available to GPT with the bidirectional representations of BERT. section 7.5.2







