Masked attention enforces causal information flow: each token gathers context from itself and preceding tokens, never from later tokens. It applies the constraint to scaled attention scores before softmax. section 2.2.1
Implement the mask in this order:
- Compute attention scores as the query matrix multiplied by the transposed key matrix. section 2.2.1
- Scale the scores, then replace every future-token position in the upper triangle with −∞. section 2.2.1
- Apply softmax so masked positions receive effectively zero probability, then multiply the attention weights by the value matrix. section 2.2.1
Why zero is not enough
For a four-token sequence, setting future scores to 0 still gives them positive softmax probability because e⁰ = 1. Setting them to −∞ removes their probability, so a token such as “is” can use only its own and preceding value vectors. section 2.2.1
Figure 2.5 The dot product of the query and transposed key matrices produces the attention scores matrix. Each element in this matrix represents the relevance of one token to another.
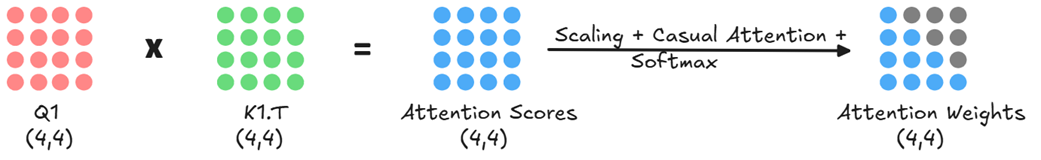
Use the attention-score matrix to locate the positions that causal masking removes before normalization. section 2.2.1









