Causal masking restricts each decoder position to tokens that came earlier, preventing later tokens from influencing next-token generation. section 3.1.1
This restriction distinguishes decoder-only models from encoder-only models, whose self-attention can use context on both sides of a token. section 3.1.1
Autoregressive generation
When generating the next token, the decoder attends to the preceding sequence while masking tokens that have not yet been generated. section 3.1.1
Figure 3.2 Transformer model architecture. It consists of an encoder stack (left) and a decoder stack (right). The encoder processes the input sequence using multi-head self-attention (MSA) and multi-layer perceptron (MLP) blocks with residual connections and layer normalization (Add & LN). The decoder processes the target sequence using masked multi-head self-attention (MMSA) and multi-head cross attention (MCA) to integrate encoder features, then projects the output to probabilities through a linear layer and softmax. Source: [9]
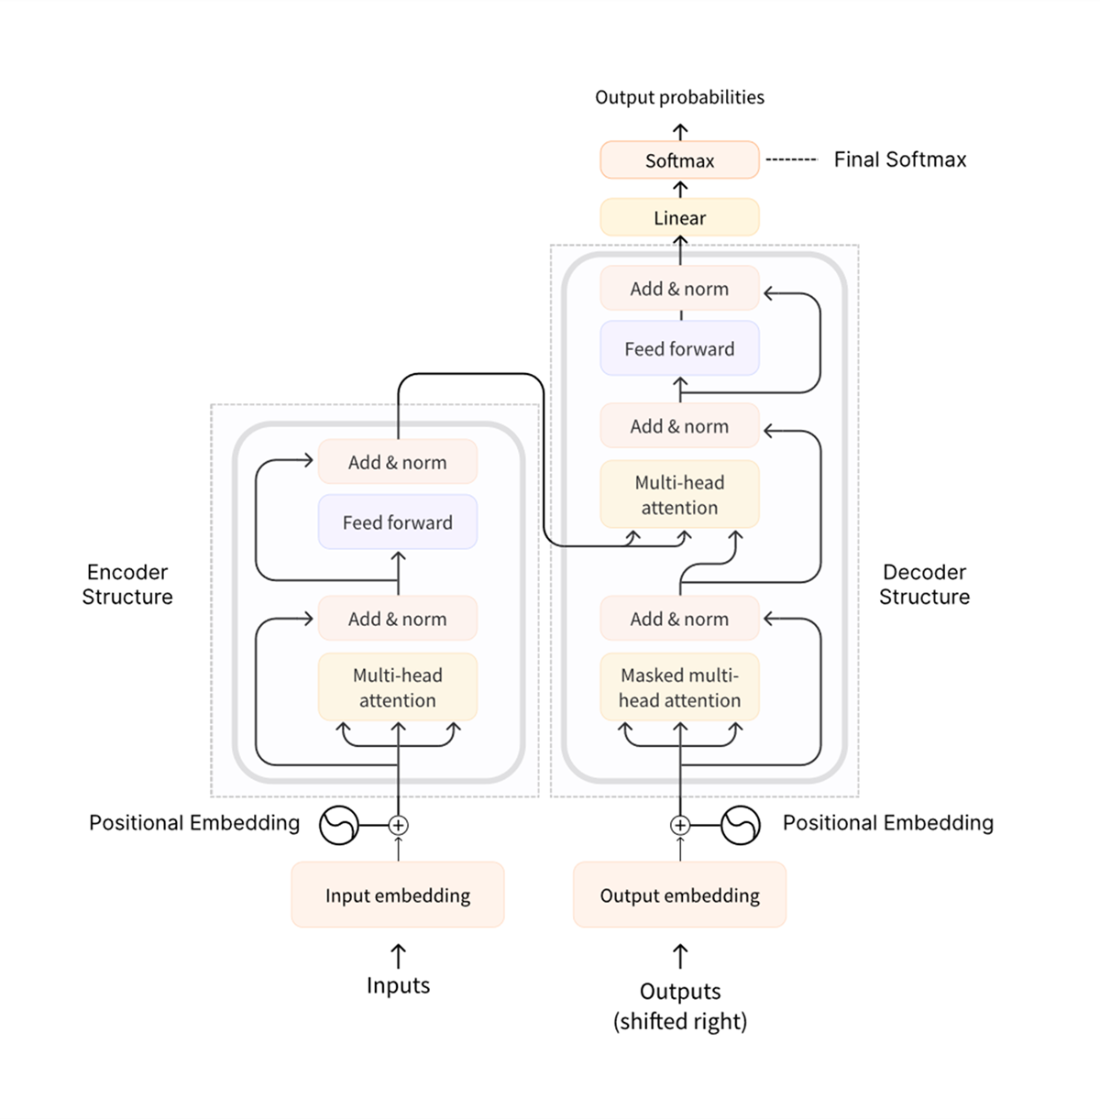
The Transformer diagram shows masked multi-head self-attention inside the decoder alongside cross-attention to encoder outputs. section 3.1.1









